Designing an Intuitive Workflow for Synthetic AI Models
Turning a fragile, code-heavy model-building process into a scalable workflow while increasing successful model creation from 65% to 87%

Intro
Gretel Workflow enables enterprise customers to connect their data sources and destinations, configure one or more synthetic AI models, and schedule recurring data-generation jobs as a single automated pipeline.
As the lead product designer for this project, I led the experience from early research and problem framing through interaction design, validation, and engineering handoff. The challenge extended far beyond adding a scheduling feature. Before we could automate the process, we first had to make the underlying model-creation experience more reliable, clarify a new and easily misunderstood product concept, and evolve a rigid linear flow into a flexible system. All while working within the constraints of the existing architecture.
I worked closely with Product, Engineering, Data Science, and customer-facing teams to identify which problems had to be solved first, what we could deliver with the system we already had, and which ideas required longer-term back-end investment. That strategy led to three progressive releases: first improving model-creation success, then validating a minimum workflow experience, and finally building a modular one-page Workflow Builder. Across the broader redesign, successful model creation increased from approximately 65% to 87%, and the product established a more approachable foundation for building and managing automated synthetic-data pipelines.
Automating a process that was not yet ready for automation
The Workflow initiative was introduced while I was already planning improvements to Gretel's existing model-creation experience.
- Step 1. Provide a local dataset.
- Step 2. Choose a synthetic model type.
- Step 3. Configure the model through a YAML editor.
- Step 4. Start and monitor model training.
- Step 5. Generate a synthetic dataset.
- Step 6. Review or download the result.
At the time, generating synthetic data was highly manual:
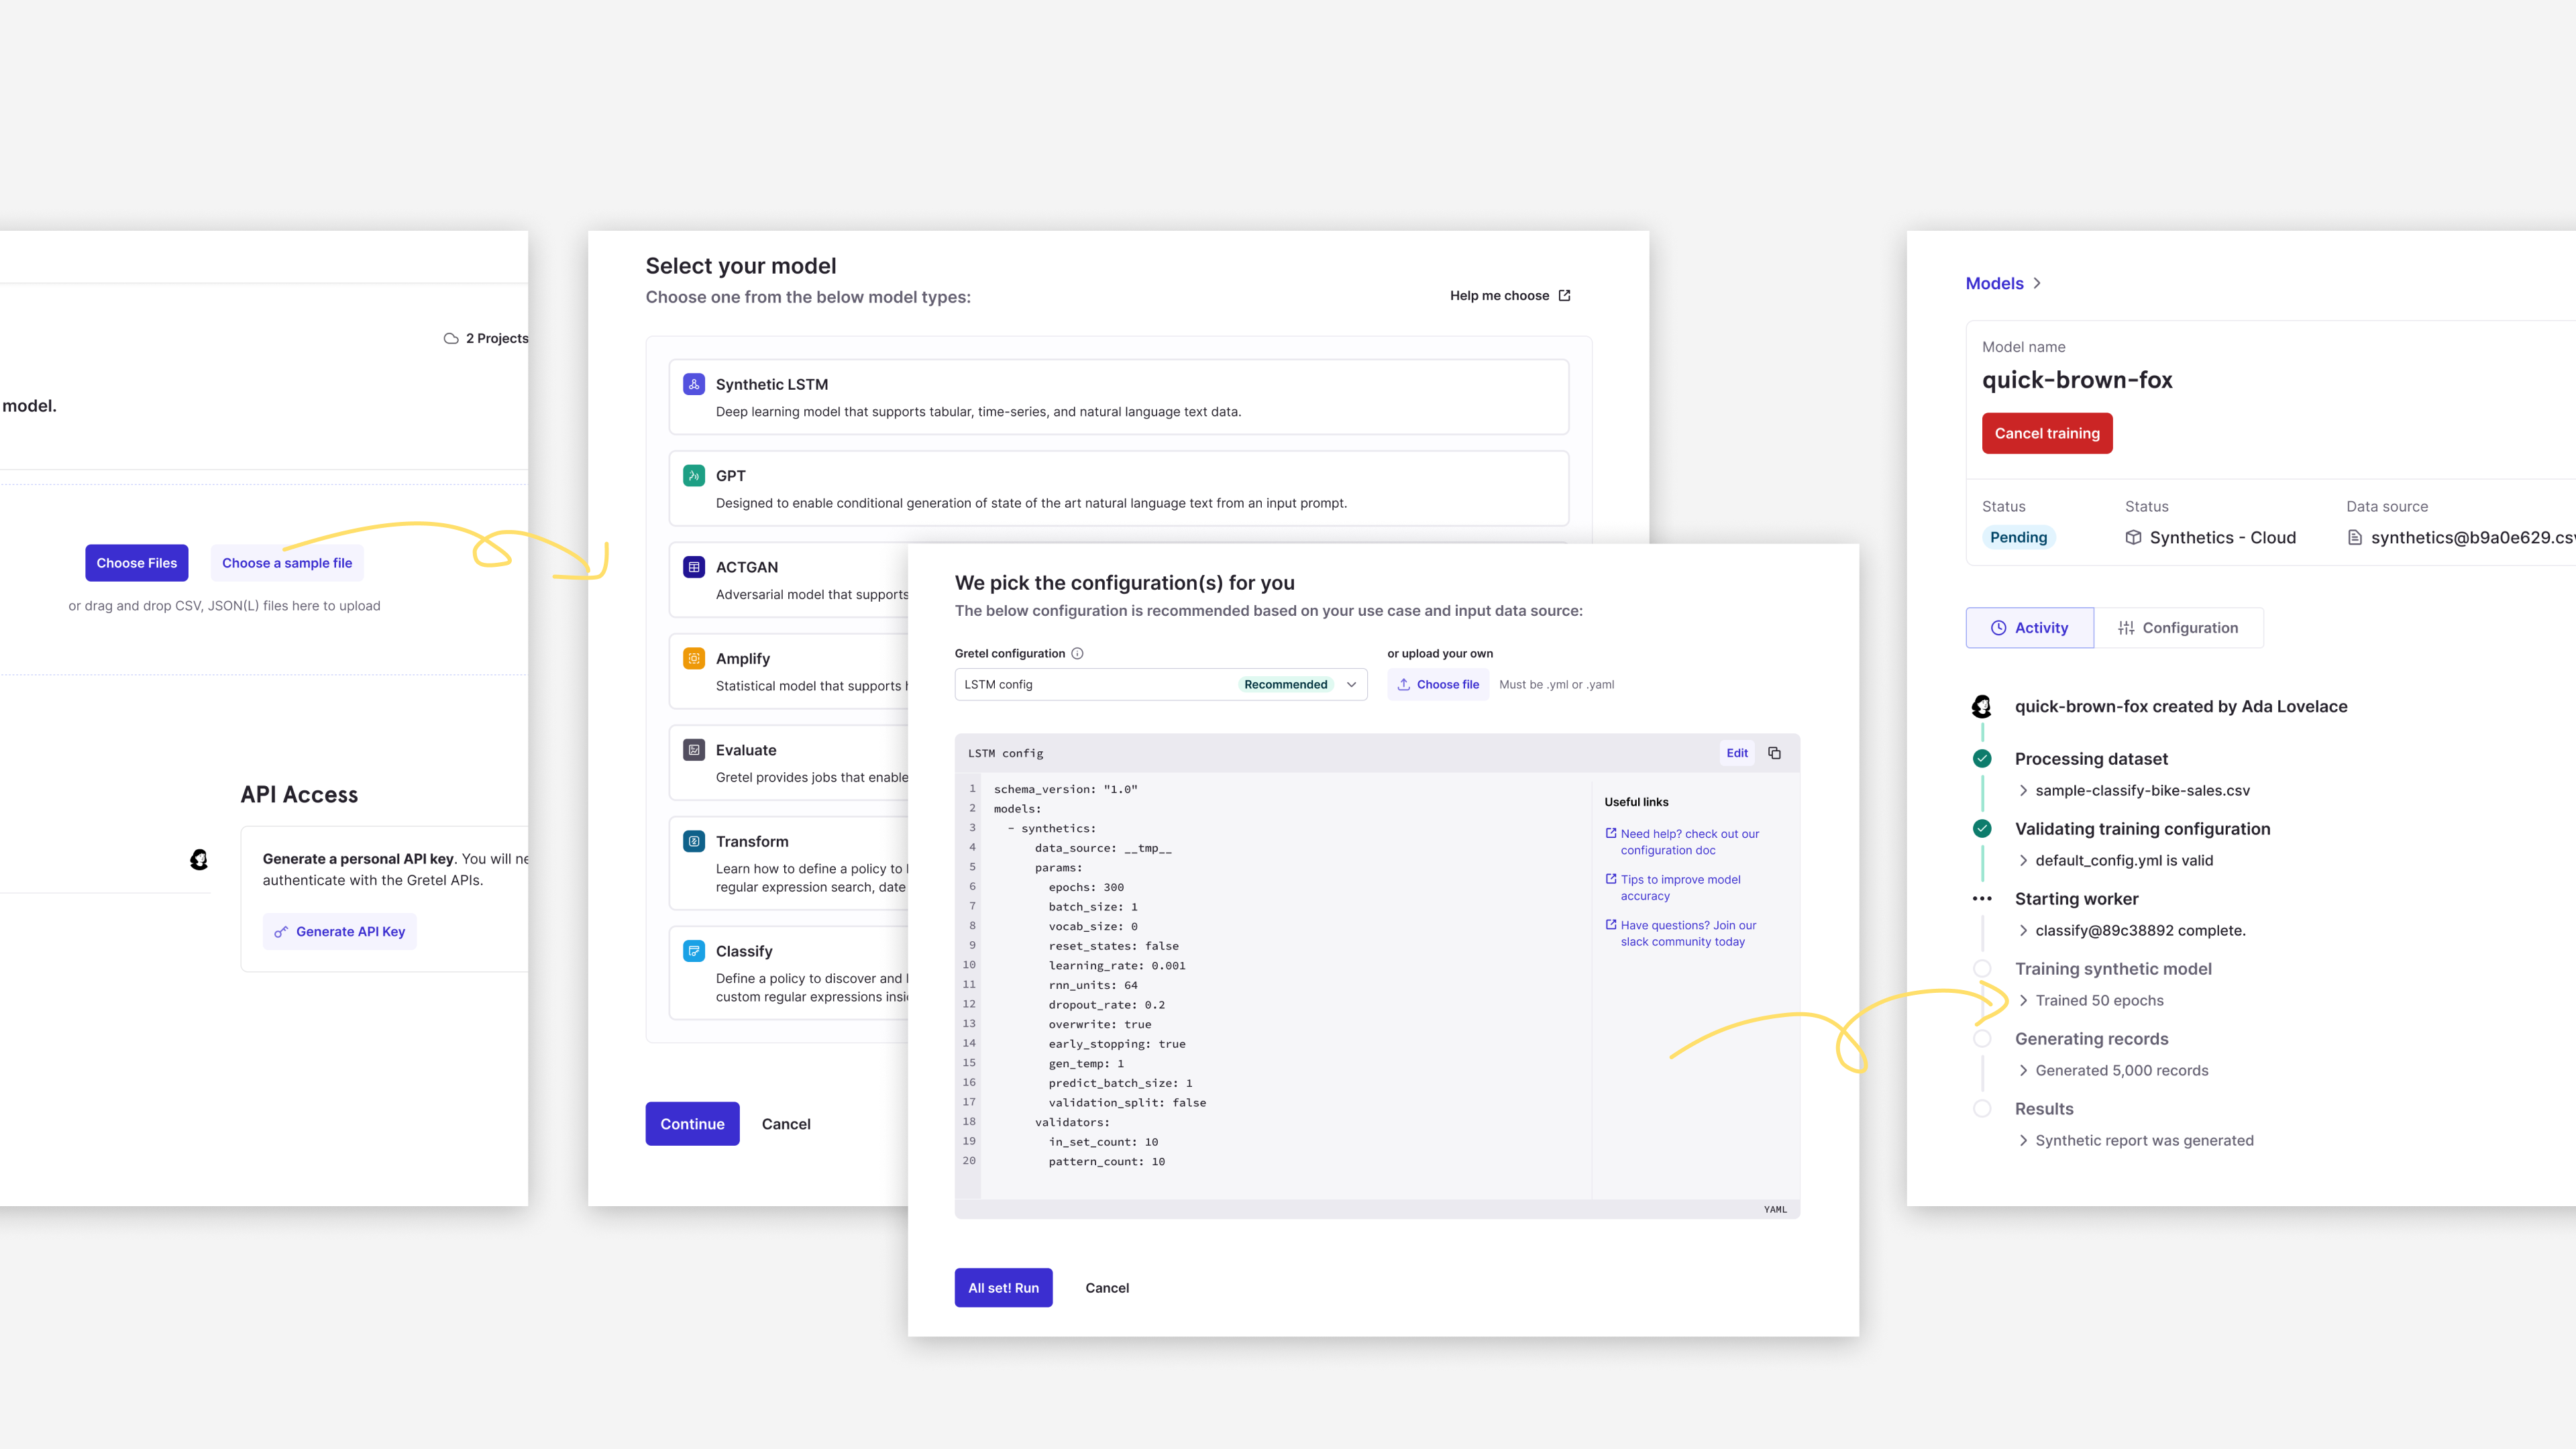
This process was workable for a single experiment, but it did not match how enterprise customers needed to operate. Their data changed continuously. They wanted to connect directly to databases and cloud storage, keep data within their own infrastructure, and generate updated synthetic data on a predictable schedule. More complex use cases could also require several models to run in sequence.
The product team's direction was the right one: transform a manual model-building process into an automated, repeatable workflow.
An ideal workflow would allow a customer to:
- Connect to an existing data source;
- Configure one model or a sequence of models for a particular use case;
- Define where generated data should go;
- Schedule the pipeline to run once or repeatedly;
- Review results, monitor status, and manage the workflow over time.
But automation does not make an unreliable process reliable. It repeats whatever is already there. If users struggled to configure one model successfully, an automated workflow could simply produce recurring failures. More time and credits would be consumed each time, with users getting nearly nothing in return.
The project therefore involved two connected challenges:
- Add a new orchestration layer for connections, scheduling, sequencing, monitoring, and recurring execution.
- Strengthen the underlying model-creation experience so a workflow could run accurately and reliably without constant manual intervention.
A multilayered product problem
Before designing the interface, I needed to untangle several layers of risk and dependency.
1. The existing model flow was not ready to be scaled
The original experience was a rigid sequence built around a single model. It relied heavily on YAML configuration, provided limited guidance, and often surfaced problems only after a user had started a long-running training job.
The model selection step created another early barrier. Research showed that many customers understood the use case they wanted to solve, but could not confidently determine which model would support it based on its name, brief description, or preset YAML configuration. There was a significant gap between how customers described their intended outcome and how Gretel organized its models, forcing users to make a technical decision before they had enough context.
Research and product analytics showed that successful model creation was low. More than 60% of model failures were associated with incorrect YAML formatting or missing required fields. Users could wait for training to begin before discovering a preventable configuration error, then investigate the failure, revise the file, and start over.
The structure also could not naturally accommodate the new relationships Workflow required: database integrations, separate input and output connections, multiple models in sequence, optional tasks, and scheduling. There was no clear place to add these capabilities without making the existing linear flow increasingly complicated.
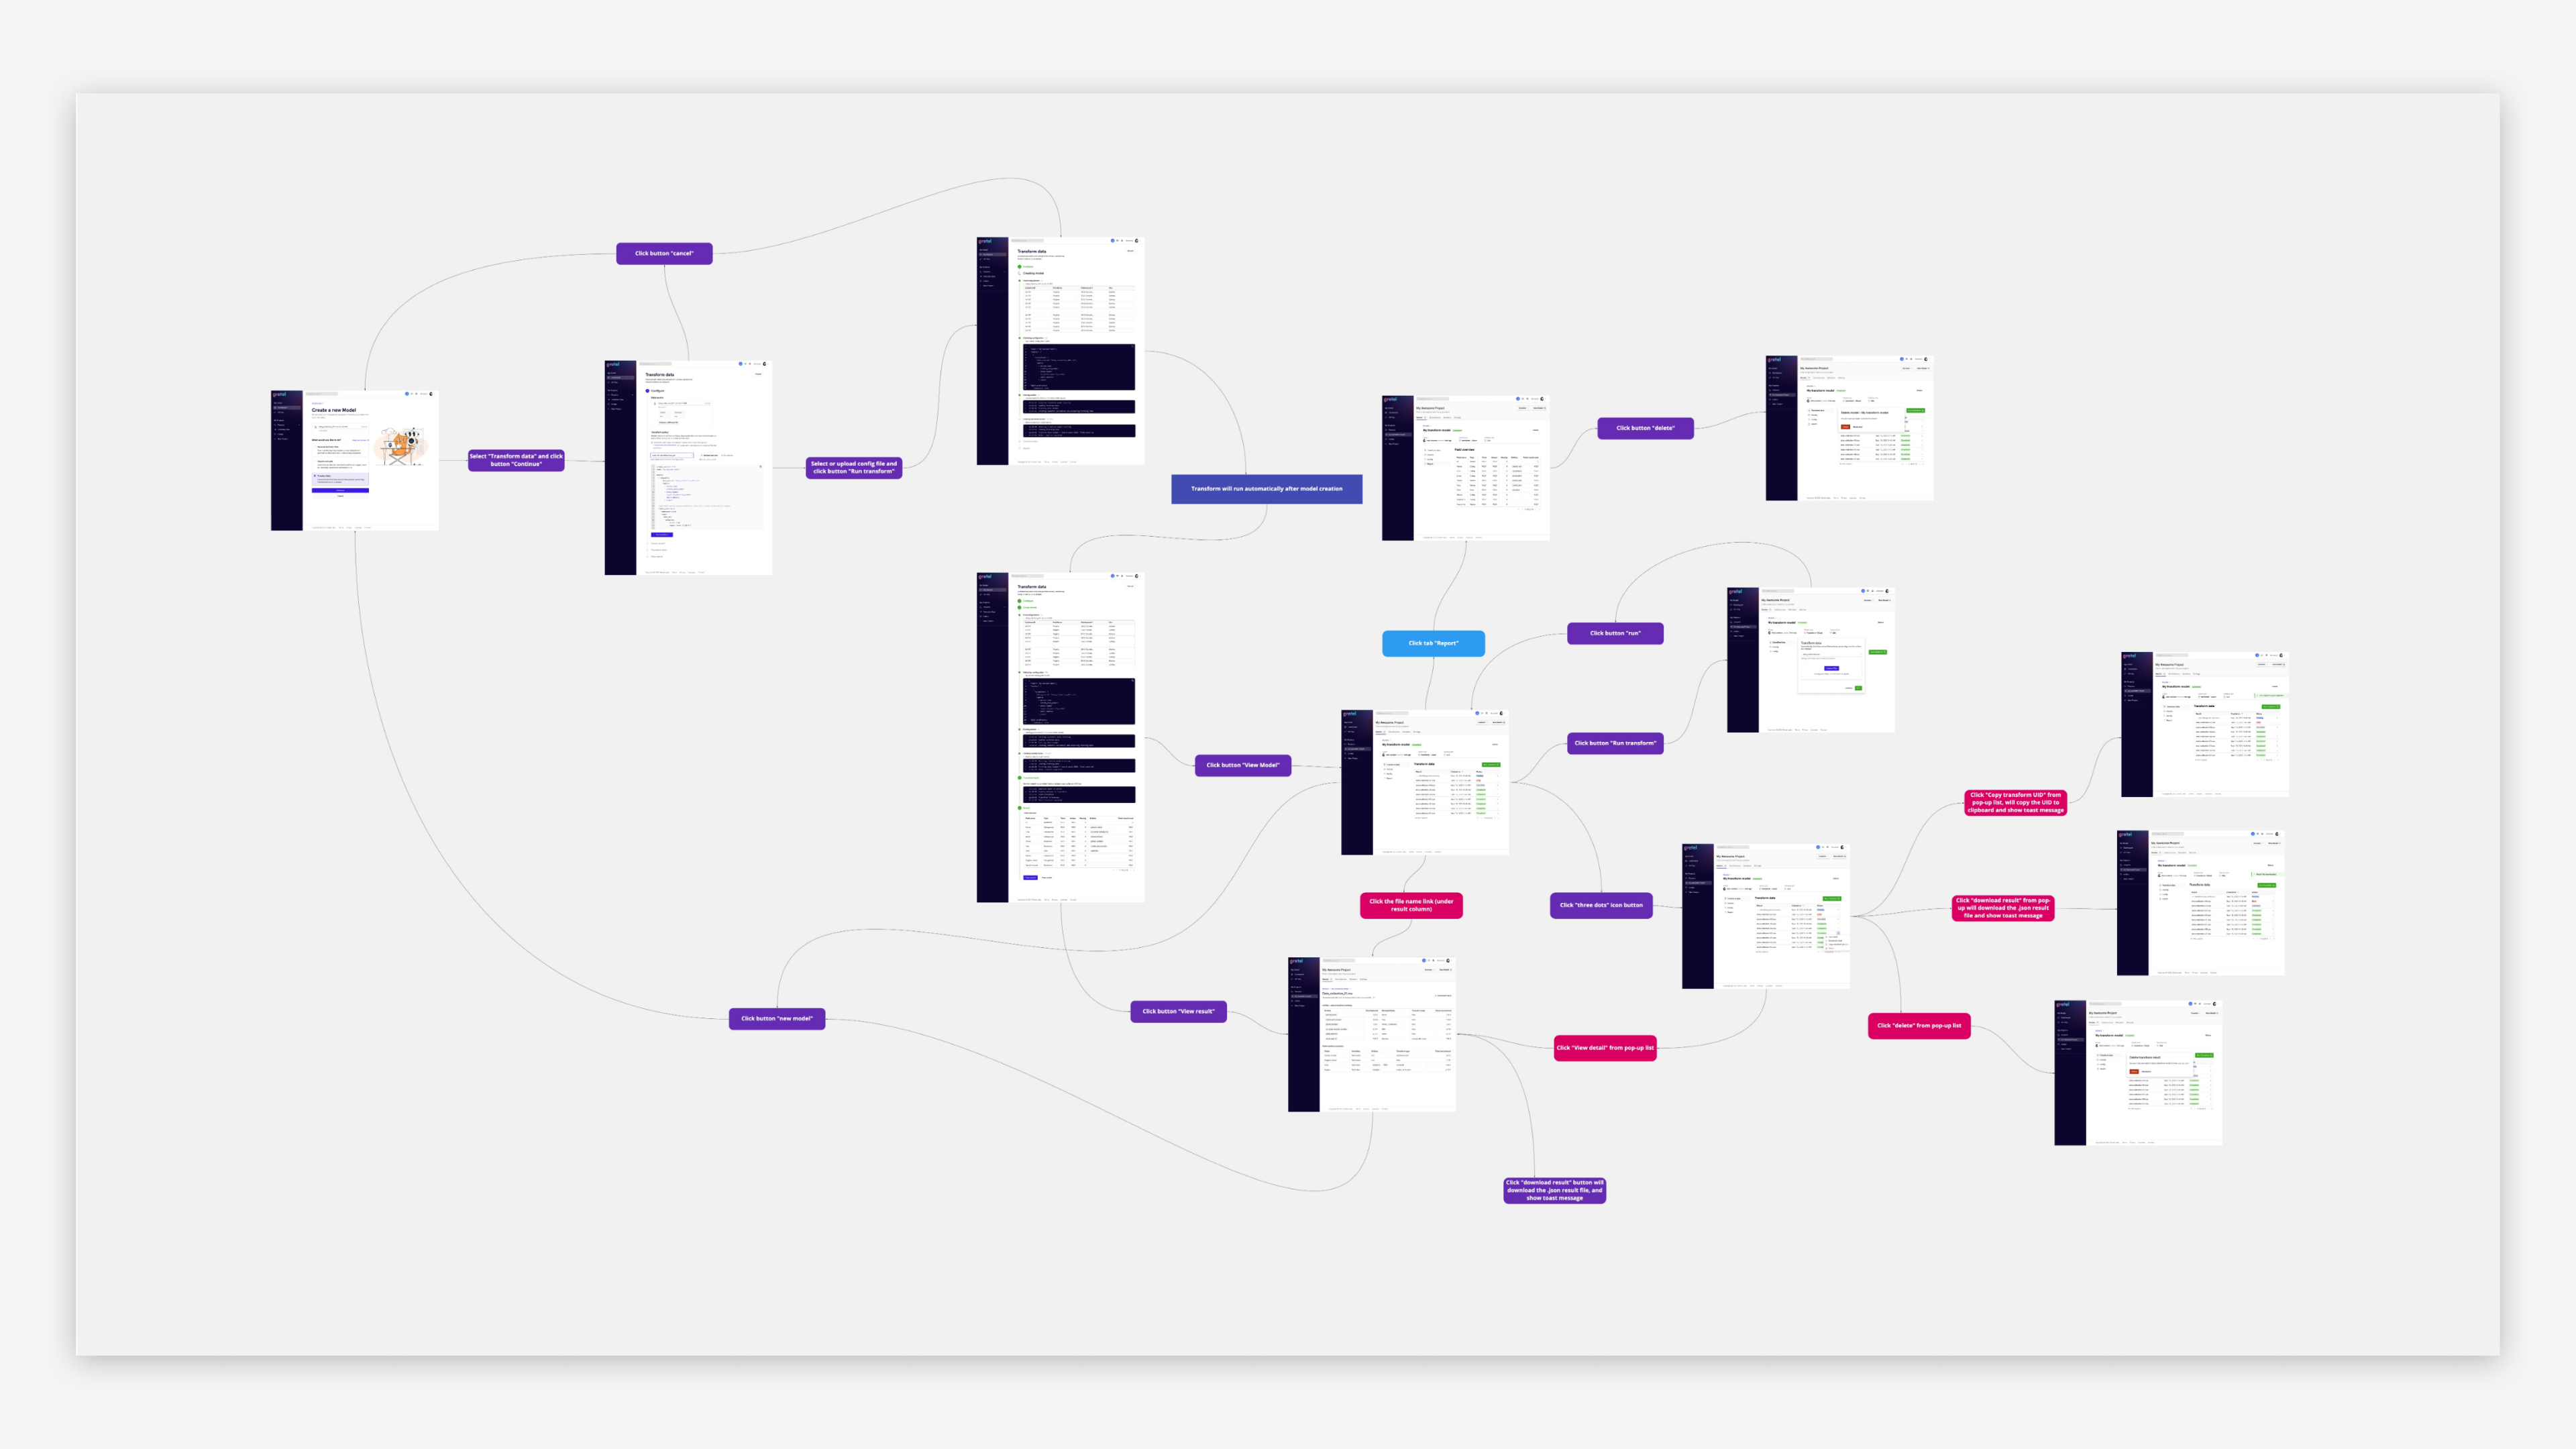
- 50% of users were confused about the distinction between "Workflows" and "Models."
Takeaway
Explaining the difference within the application is challenging because workflows operate on a higher level of abstraction than models, making it difficult to differentiate them in a clear and intuitive way.
- 30% struggled to understand how workflows function.
Takeaway
Workflows involve several technical tasks, such as chaining multiple models, managing input and output connections, handling automation, and more. These complex processes can overwhelm users, especially those without technical expertise, making it difficult for them to grasp the full functionality.
2. Workflow introduced a new mental model
A model and a workflow are closely related, but they are not interchangeable. A model defines how synthetic data is trained and generated; a workflow coordinates models with data connections, destinations, schedules, and other tasks.
My assumption was that this similarity would cause confusion, and research confirmed it:
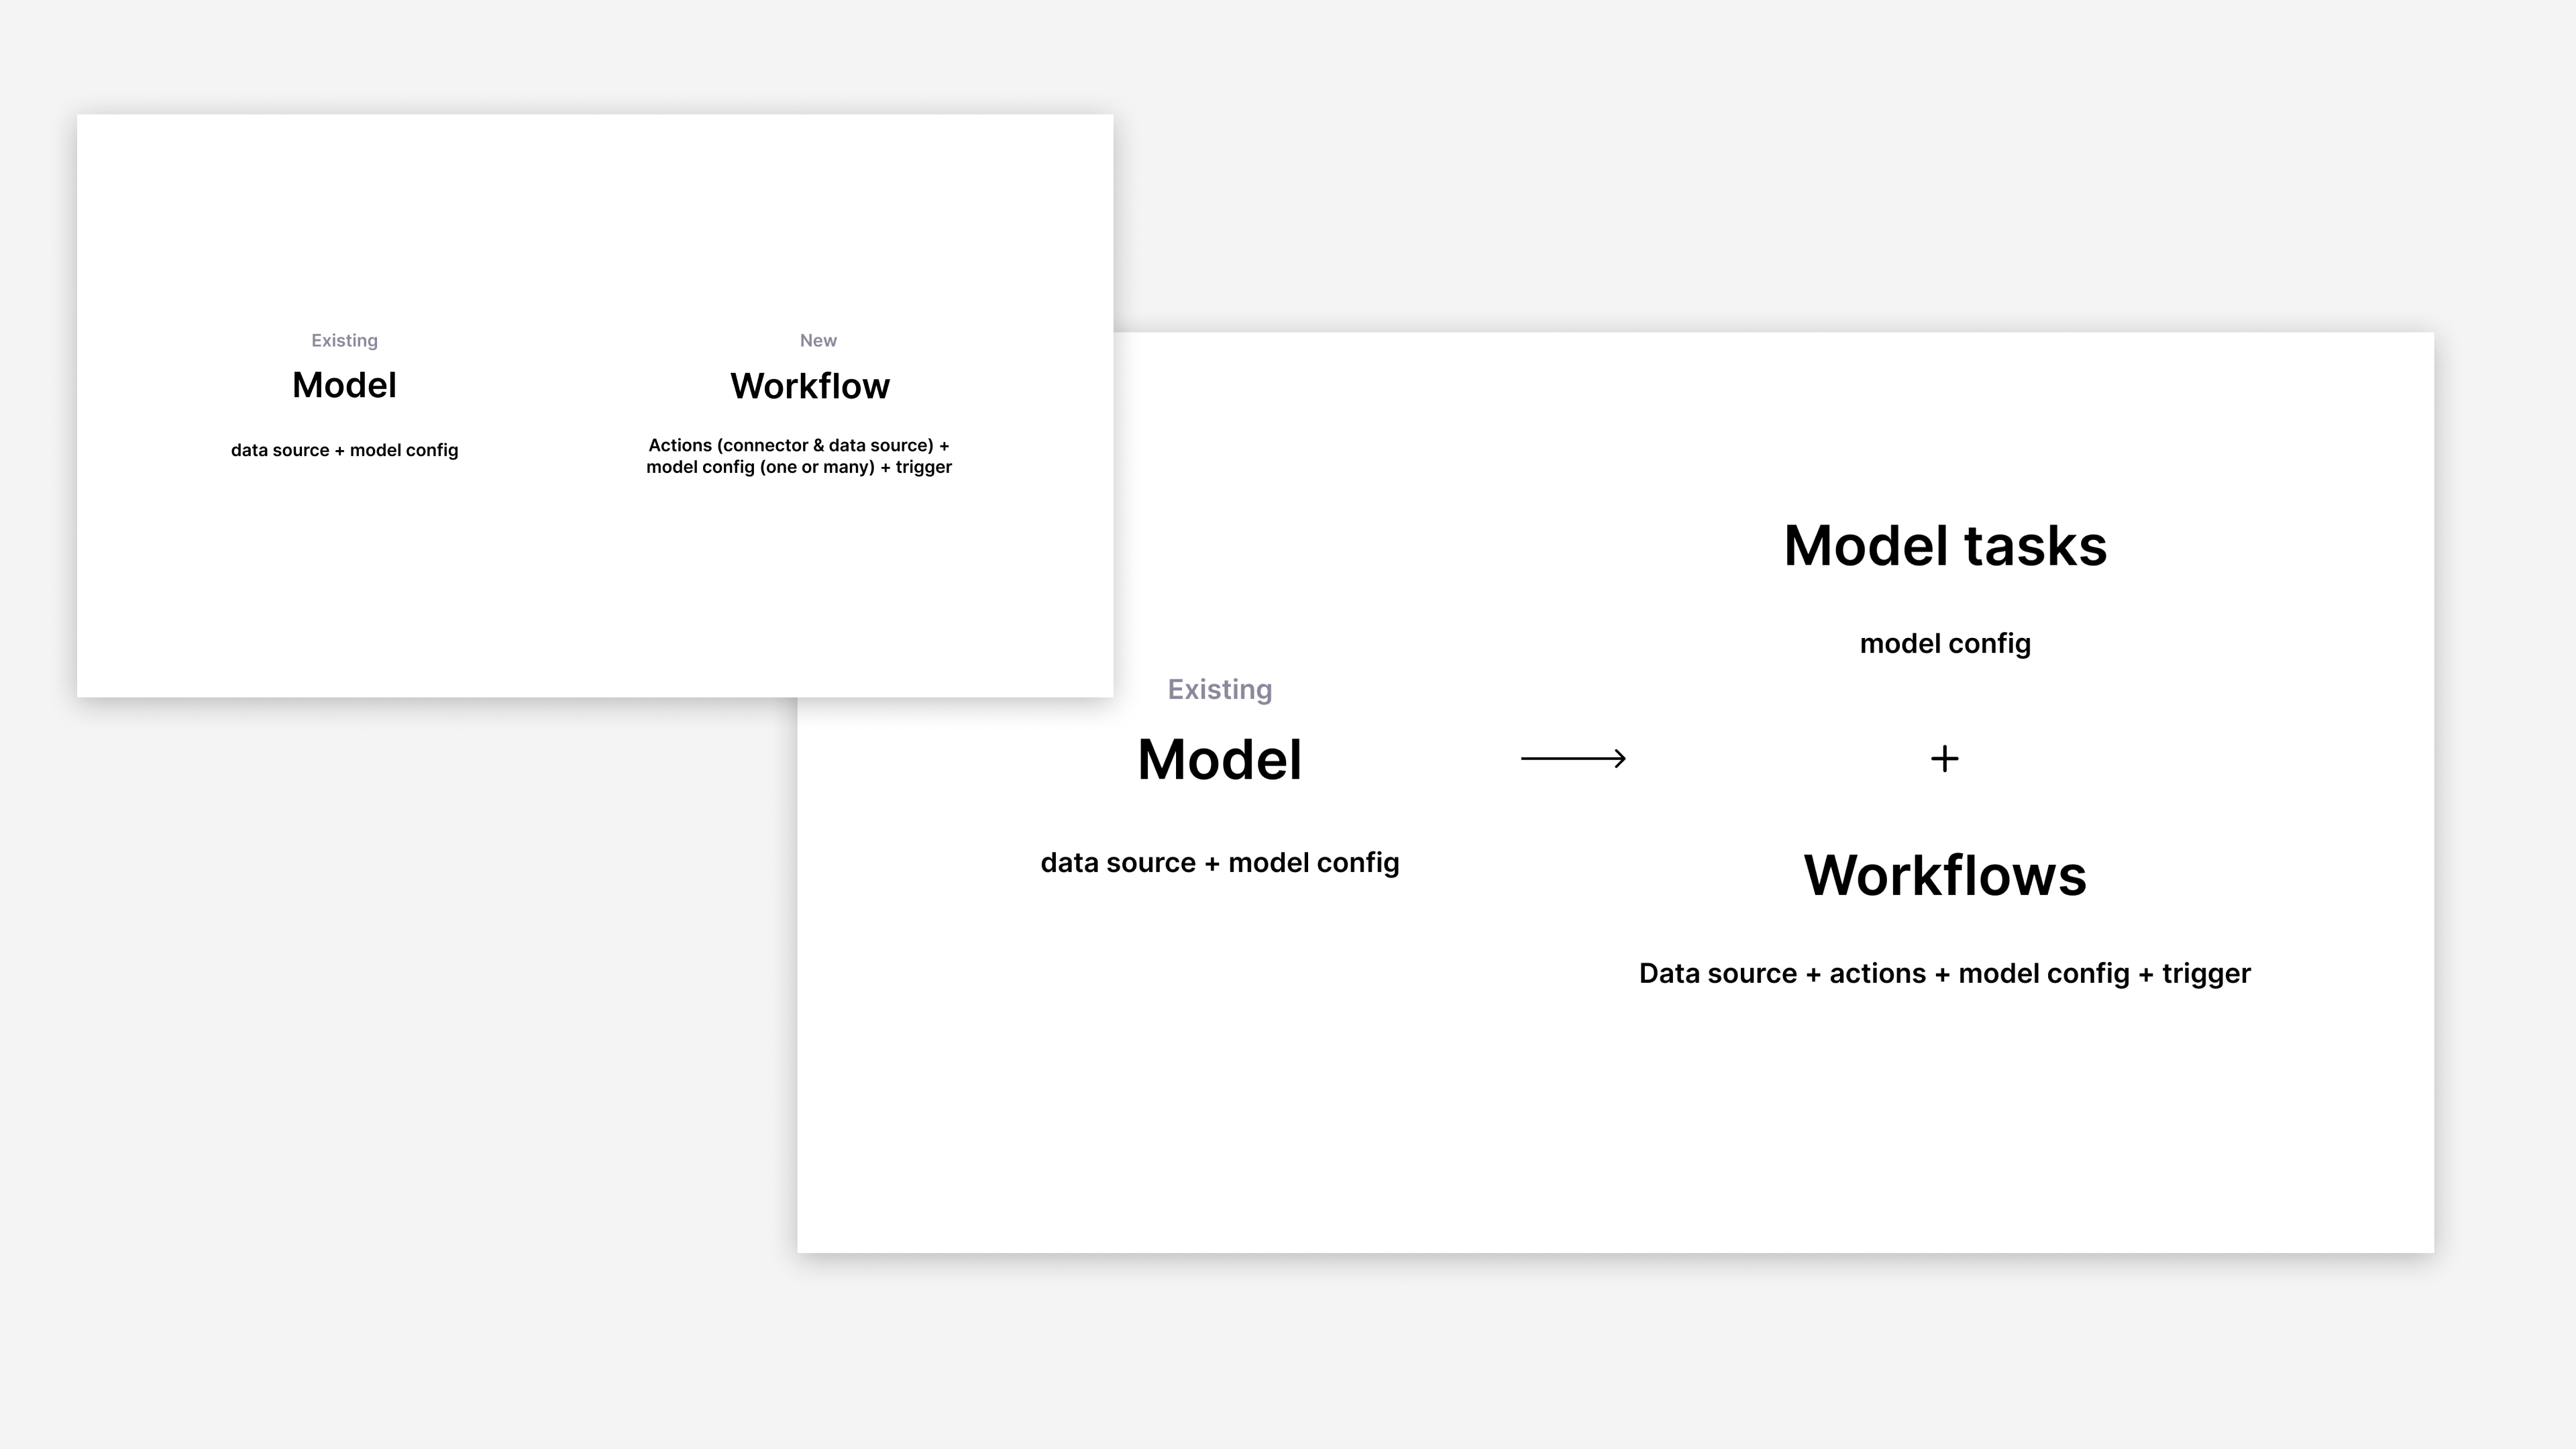
We were asking users to understand both a new product concept and a more complex system structure at the same time. If the interface simply exposed every technical object and dependency, it would transfer the architecture's complexity directly to the user.
3. Automation raised the standard for reliability
A manually initiated failure is frustrating. A scheduled failure that repeats unnoticed is much more costly.
Workflow jobs could require more time and credits than a single manually created model, especially when several models or large datasets were involved. Users therefore needed greater confidence before activating a workflow. They had to know whether each step was configured correctly, what had failed, where the problem occurred, and how to recover without rebuilding everything.
The existing product did not yet have an error-handling system designed for this. Creating one would require experience design as well as back-end support for validation, status, metadata, and actionable error responses.
4. The ideal experience depended on deeper platform changes
A fully flexible builder could not be delivered through interface changes alone. Supporting reusable steps, model chains, independent validation, and flexible connections required changes to APIs, metadata, and back-end structure.
That created an important planning constraint:we needed to deliver value with the existing linear system while aligning toward a more flexible long-term architecture. Designing only for current technical limitations would lead to a dead end; designing only for the ideal future would delay customer value and learning.
Framing the right problems before designing the solution
I began by gathering as much context as possible from product analytics, support tickets, customer conversations, usability sessions, Hotjar recordings, internal testing, and ongoing discussions with Product, Engineering, Data Science, and customer-facing teams.
Rather than organizing the work around a list of requested features, I used six questions to frame the product plan.
- What is the smallest useful version of automation?
Worked with Product and Engineering to identify the minimum loop that would provide genuine workflow value: connect data, configure a model, define an output, and schedule the process to run. This gave us a viable starting point without waiting for the full multi-model vision.
- Who needs Workflow, and which integrations matter first?
Enterprise customers had different infrastructures and use cases, so “support database connections” was not specific enough. We needed to understand which data sources and destinations were most important, how much setup they required, and where we could simplify without obscuring privacy or infrastructure requirements.
- What must users know to create the right workflow for their use case?
I examined the decisions that most affected model selection, output quality, and successful execution. Customers often understood the outcome they wanted, but not which model or configuration would best support it. This helped me identify which decisions users actually needed to make. Technical details could then be translated into guided choices, defaults, and contextual support. The goal was to build confidence throughout the workflow, starting before users even began.
- Which existing failures would undermine automation?
The low model-creation success rate and weak YAML error handling were not separate usability issues; they were foundational workflow risks. Fixing them became a prerequisite rather than a secondary improvement.
- How flexible could the current platform become?
I worked closely with engineers to understand the existing metadata and API structure. We identified what the system already supported and what could be extended incrementally. We also identified where the linear flow required deeper architectural changes. This helped me design within current technical constraints while keeping the long-term experience in mind.
- How should we prioritize everything?
I considered user impact, workflow reliability, technical feasibility, dependencies, and learning value together. The best first release was not necessarily the most visually complete one; it was the release that reduced the greatest foundational risk and taught us the most about what to build next.
What the research changed
- The ideal flexible workflow required significant back-end work, so the team needed an incremental path that could use the existing flow while the new architecture was developed.
- Model-creation success had to improve before recurring automation could be trusted.
- Users needed help distinguishing a model from the larger workflow that contains it.
- Customers understood the use case they wanted to solve, but often struggled to translate that intent into the right model type and configuration.
- Many customers were not comfortable writing or debugging YAML, even when they understood their data and desired outcome.
- The minimum valuable workflow needed a data connection and basic scheduling tied to the existing model process.
- Workflow required earlier, more granular validation and error recovery, but some of that capability depended on new back-end support.
- Because workflows could consume more credits than a single model run, preventable failures would carry greater customer cost and damage trust.
- The interface needed to serve less-technical customers without taking advanced control away from experienced users.
This framing produced several decisions that shaped the roadmap:
Turning context into a phased product strategy
The roadmap was not simply V1, V2, and V3 in order of visual sophistication. Each version reduced a different kind of risk.
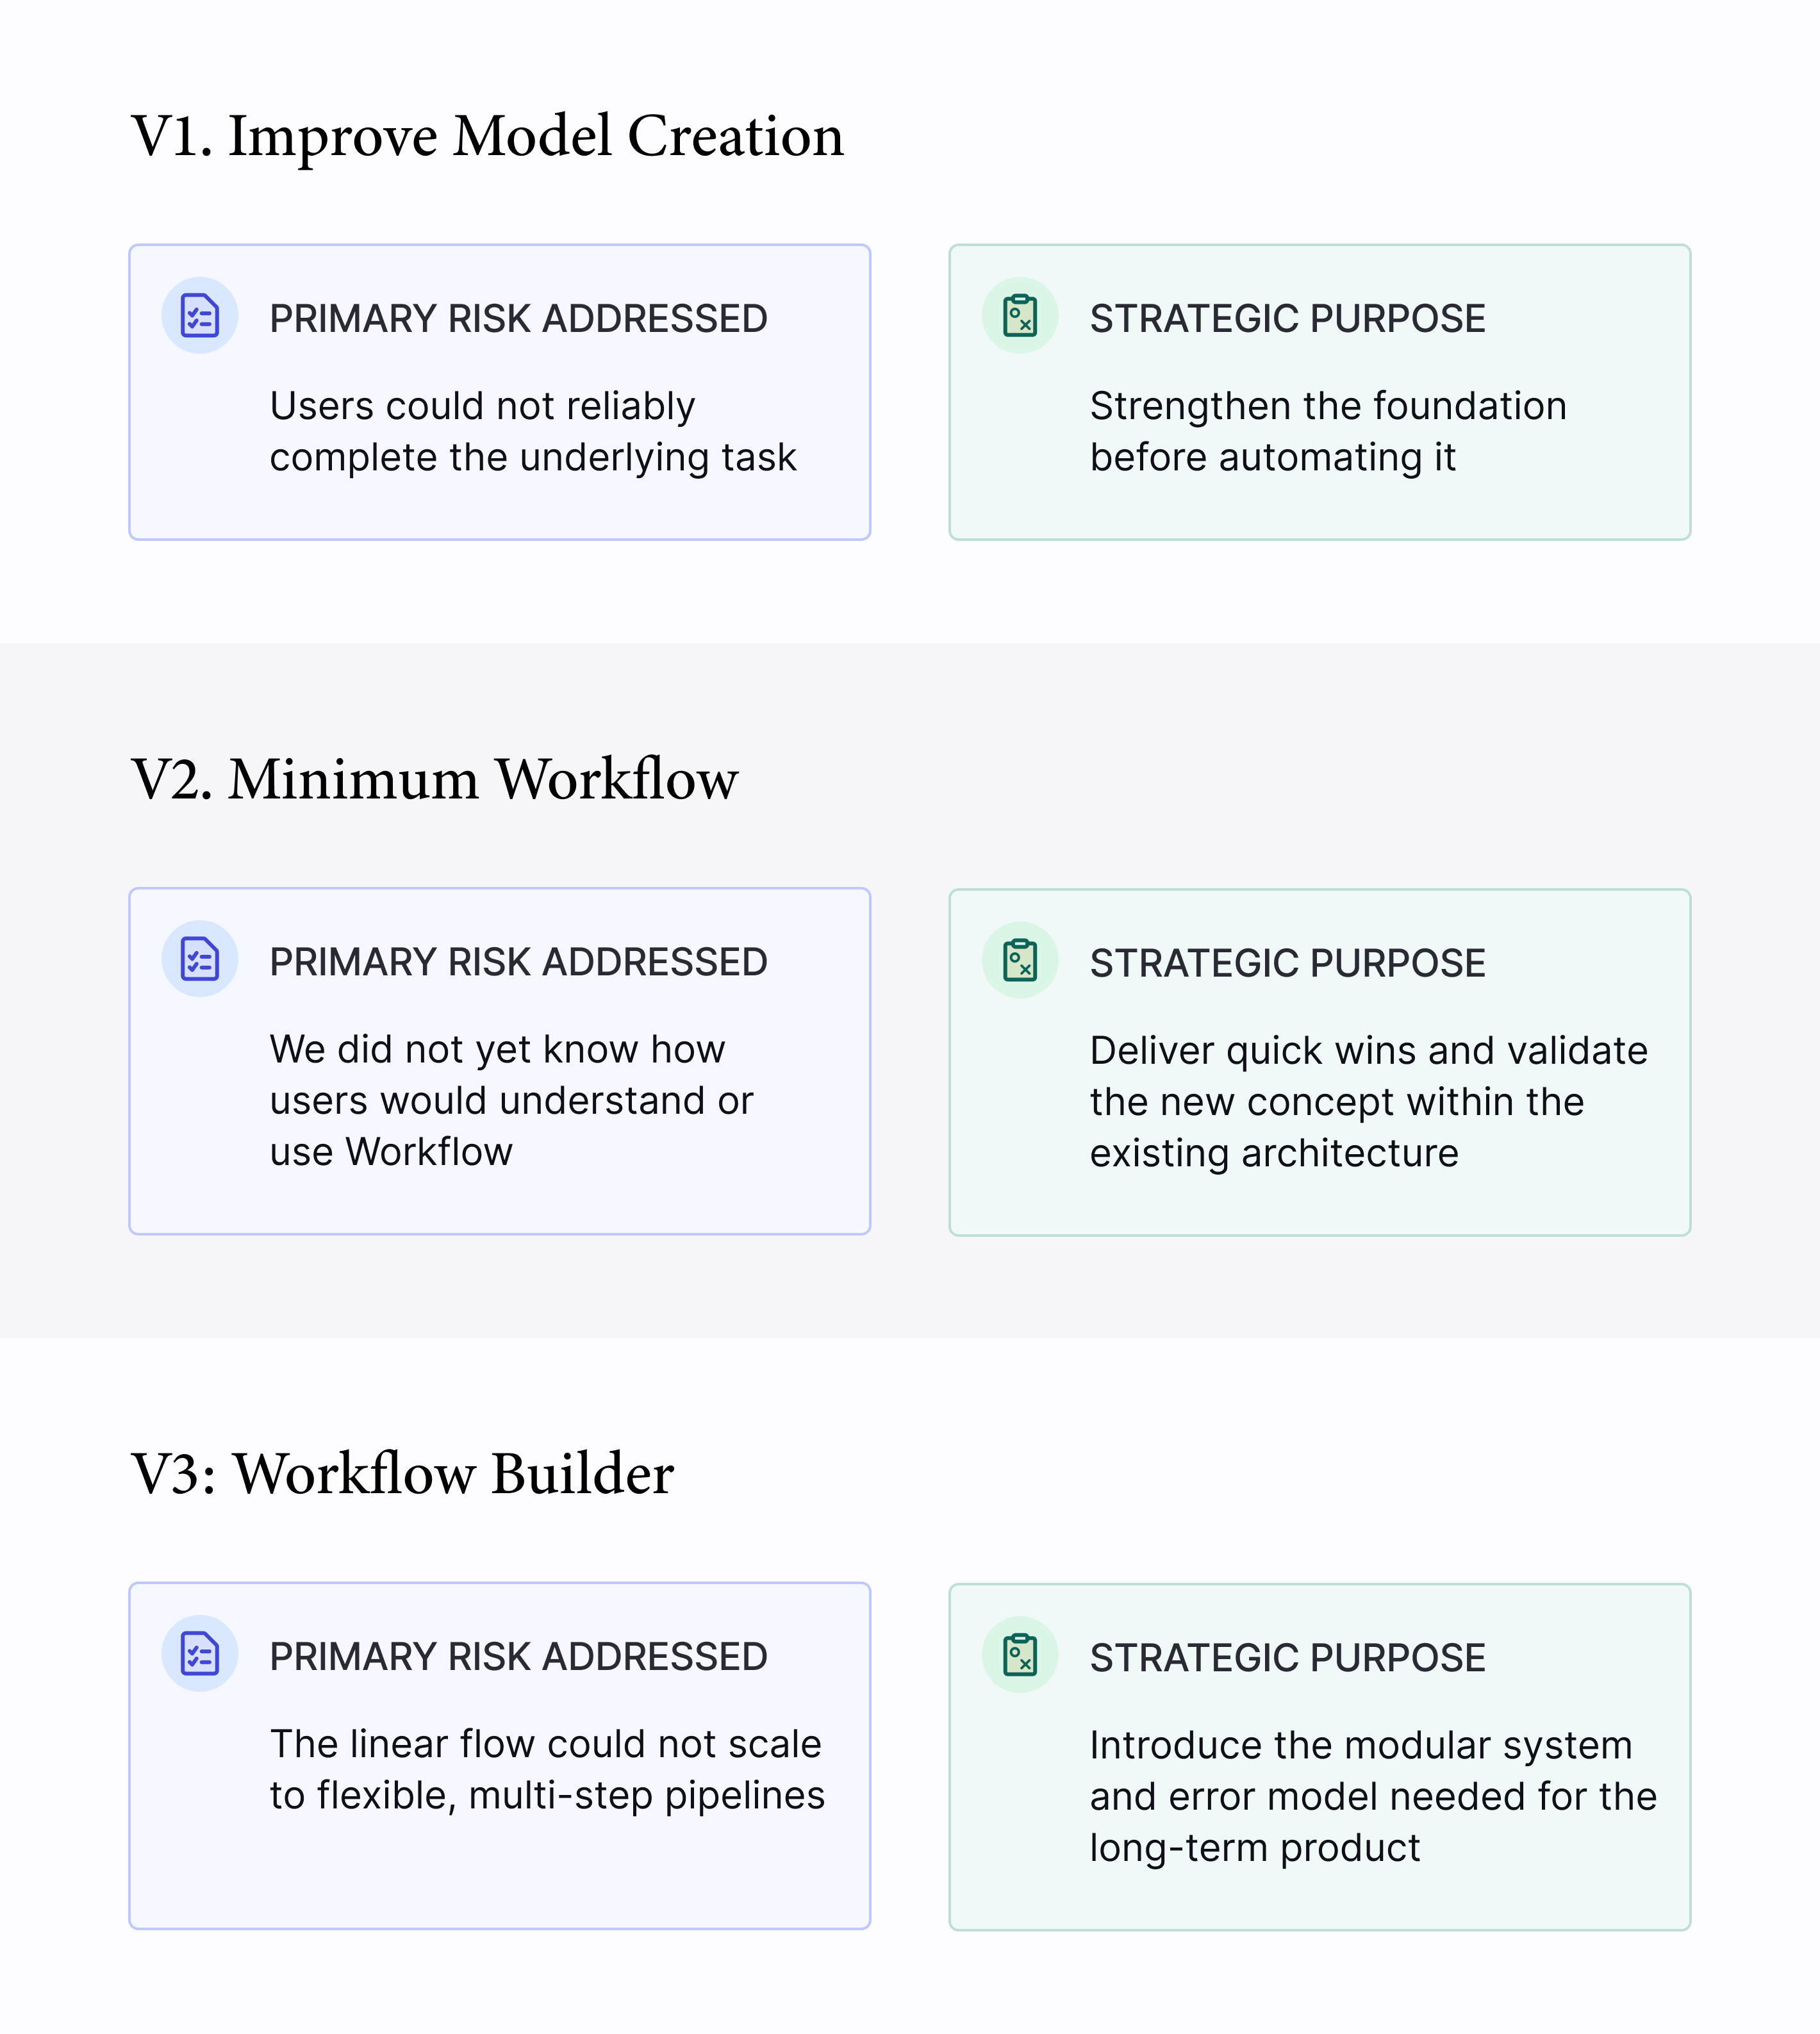
While V1 and V2 were being implemented and tested, I was already exploring V3 with the back-end team. We discussed the desired workflow structure, metadata, APIs, validation requirements, and implementation sequence in parallel. This let design inform the architecture early and allowed the experience to progress as soon as the technical foundation was ready.
V1: Make the underlying model experience more reliable
My first priority was to create a guided path that helped users complete their first model successfully. This version addressed the most immediate blockers with changes that were feasible within the existing architecture.
Start with the use case, not the model type
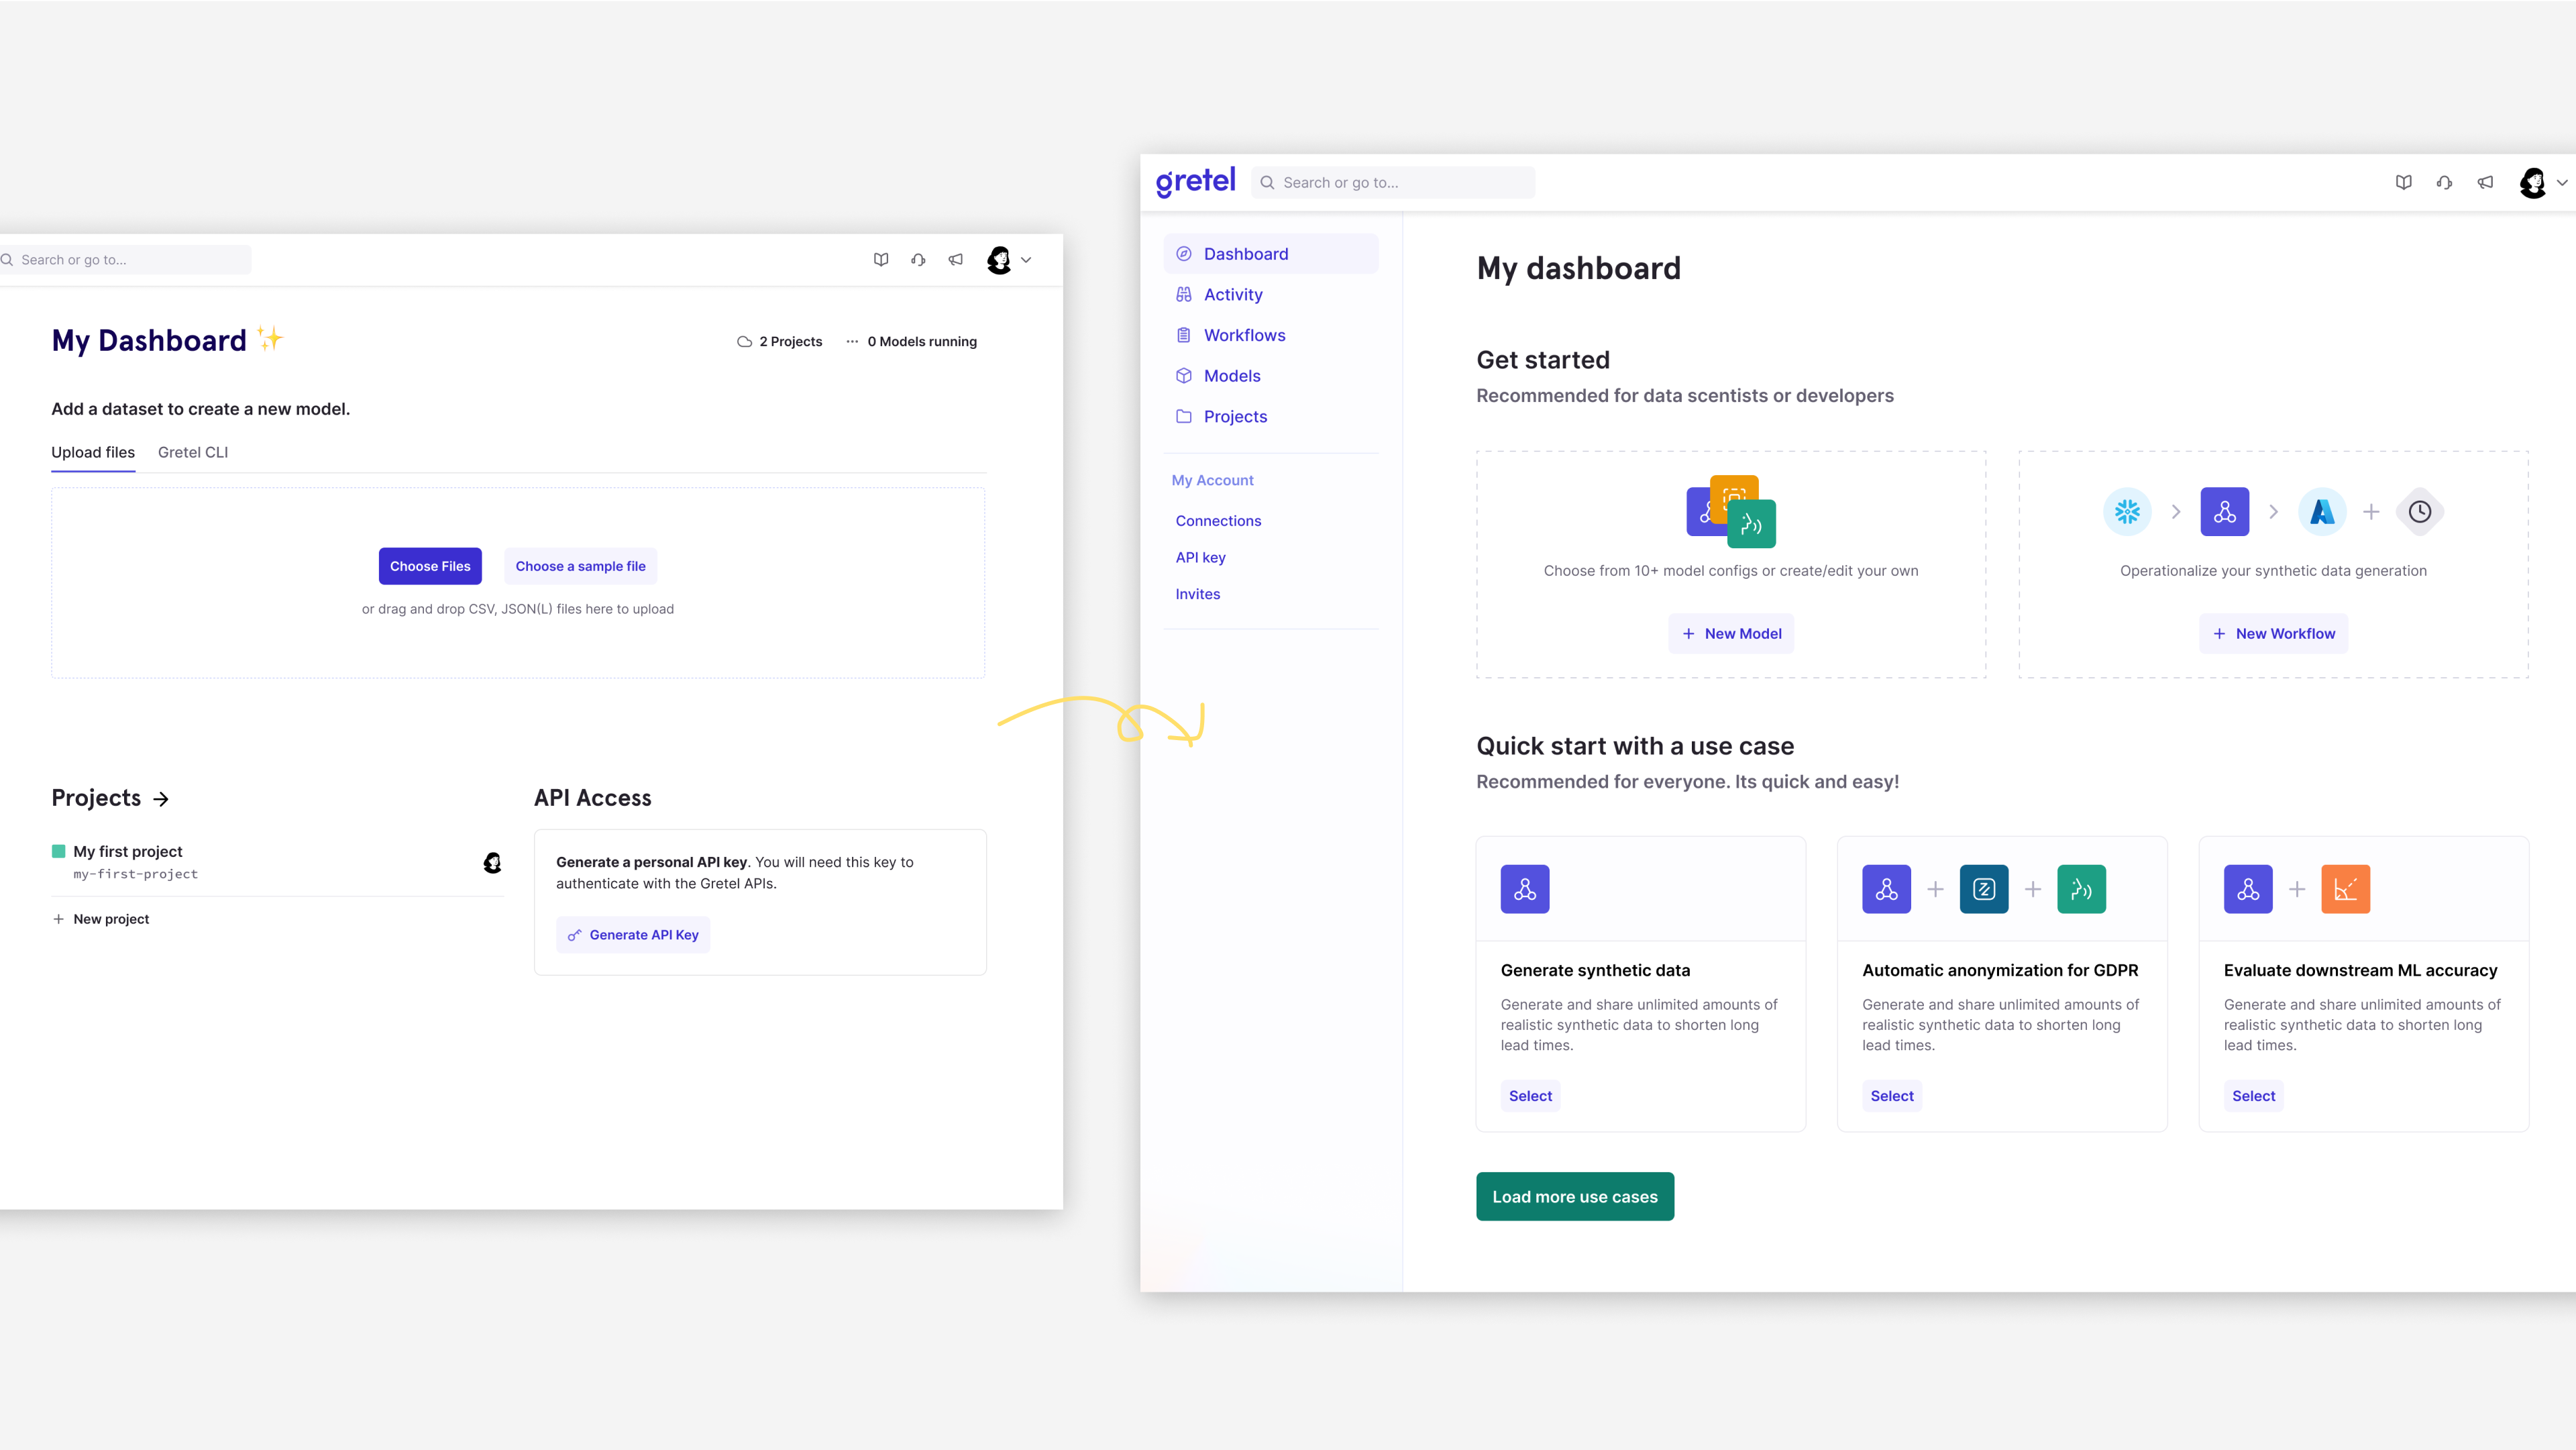
New users often knew the outcome they wanted but did not know which technical model type to select. I replaced that initial decision with plain-language use-case cards. When a user selected a use case, the product chose the appropriate model type behind the scenes.
This reduced the first layer of technical decision-making and created a pattern that could later support more complex workflow templates, including use cases involving multiple models.
Remove the empty data starting point
Hotjar recordings and internal testing showed that new users often dropped off immediately because they did not have a suitable dataset ready. I introduced curated sample datasets so they could experience the full model process before connecting or preparing their own data.
The result showed that more than 85% of new users started with a sample dataset, suggesting that the seemingly simple upload requirement had been a meaningful barrier to learning the product.
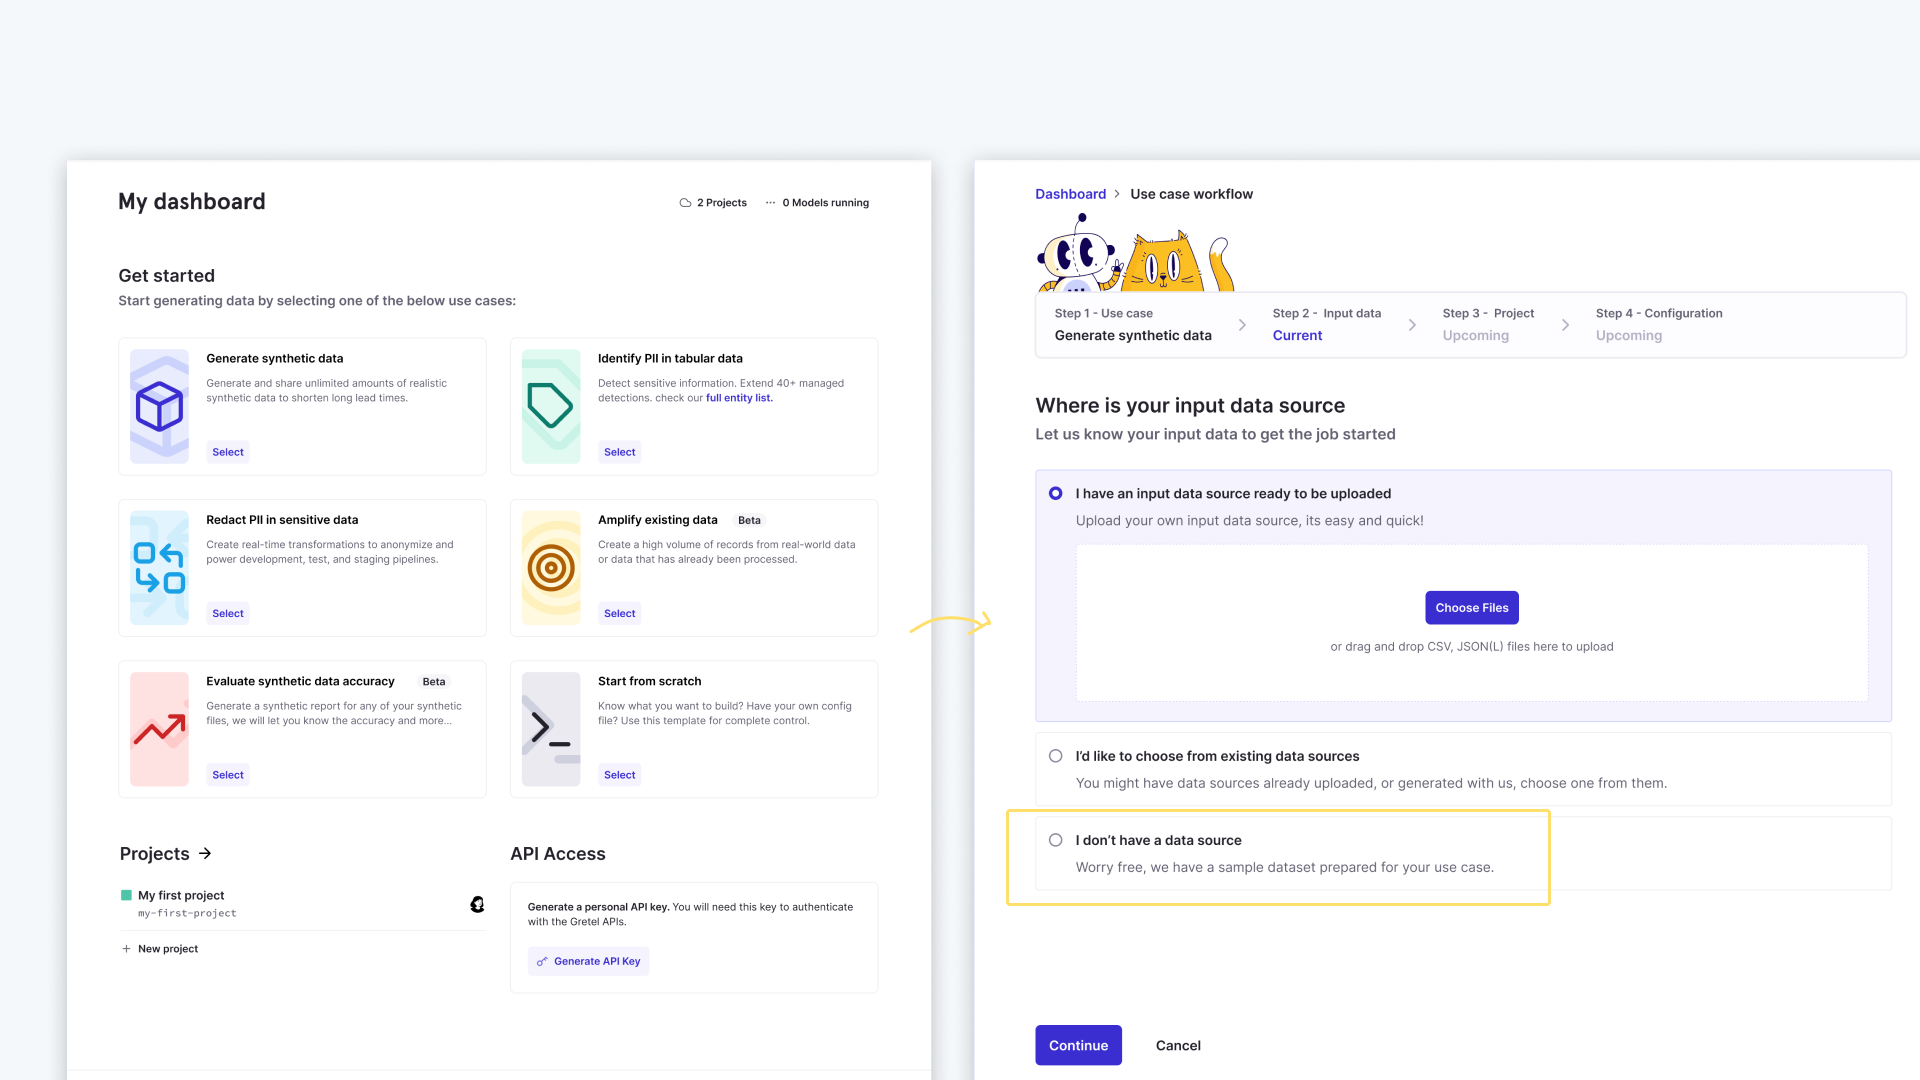
Guide users through an opinionated flow
I introduced a stepper with summaries and clearer next actions. The goal was not maximum flexibility at this stage; users first needed a dependable path through an unfamiliar task. Making the sequence explicit reduced ambiguity and helped users understand how each decision contributed to the eventual model.
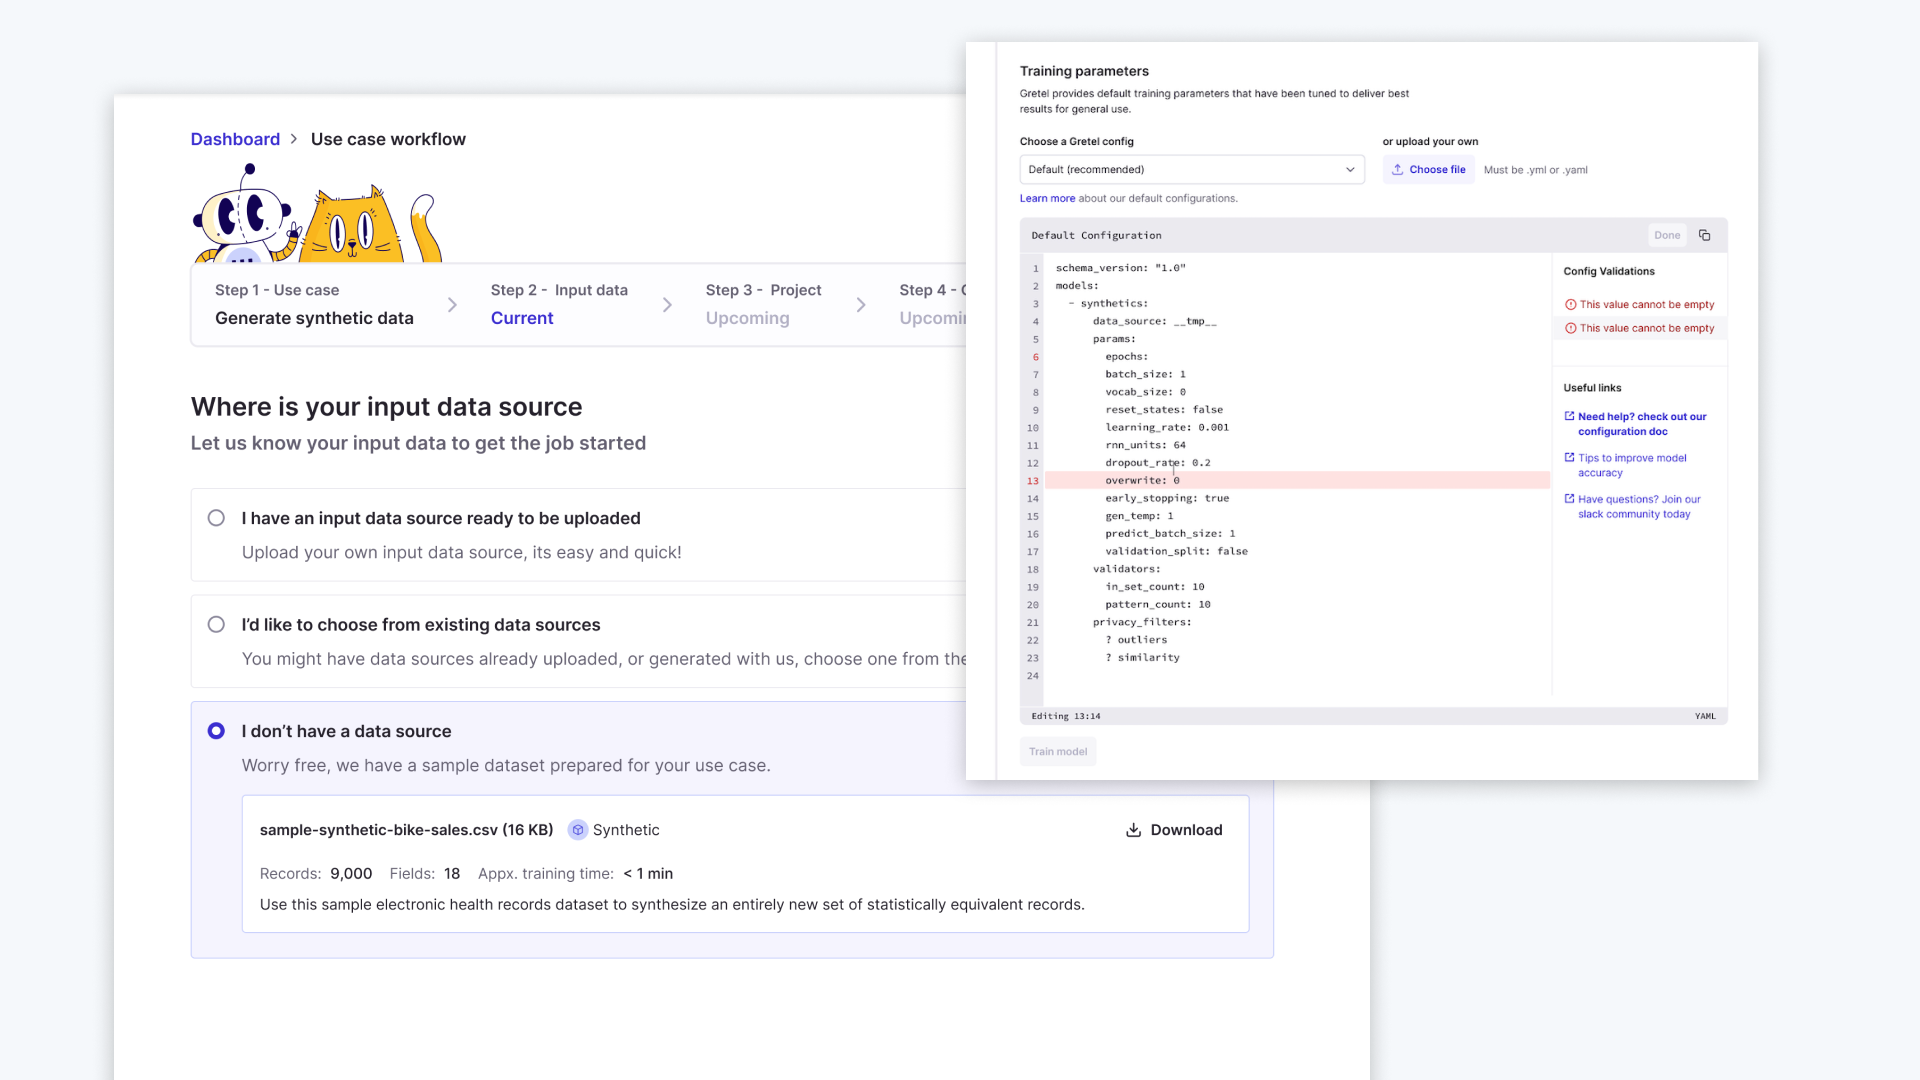
Catch YAML mistakes before training
Because incorrect formatting and missing required fields contributed to a large proportion of failures, I added syntax checks, required-field guidance, and more actionable inline errors to the YAML editor.
This was a deliberately pragmatic decision. Replacing all code-based configuration would take time, but earlier validation could deliver significant value with comparatively limited engineering effort. It also established the first layer of the more robust error-handling system Workflow would eventually require.
V2: Validate a minimum workflow using the existing system
While V1 was being completed, the team wanted to bring Workflow to customers quickly. The flexible builder and supporting back-end structure were not ready, so I extended the existing stepper to support the minimum workflow loop.
Users could connect the necessary steps around model creation and automate a basic synthetic-data job through a familiar interface. This version was intentionally transitional: it reused the linear flow rather than pretending we already had the flexibility required for the final system.
That compromise still created important value. It allowed us to:
- deliver basic automation earlier;
- observe where users confused workflows with individual models;
- understand which instructions and terminology required more explanation;
- test whether the existing UI could support connections and scheduling;
- gather evidence for the structure and capabilities V3 would need.
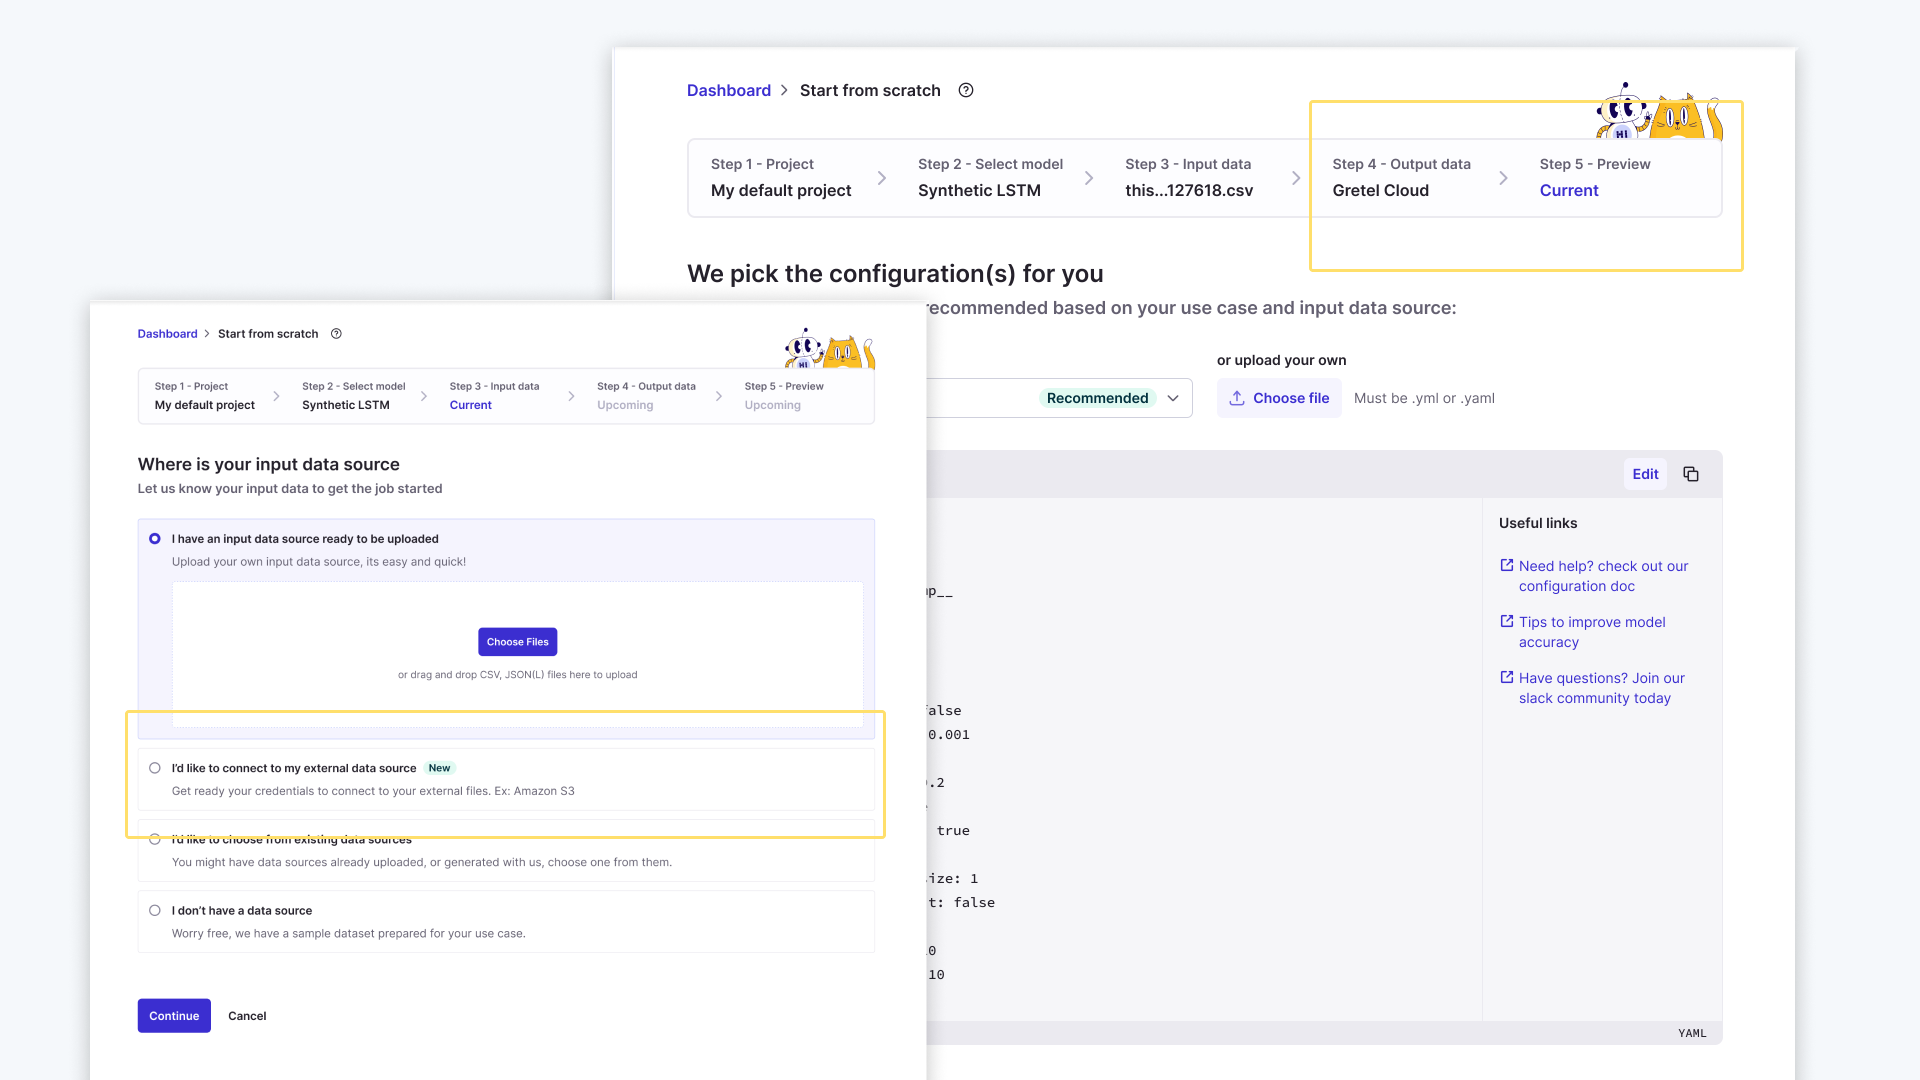
V2 reinforced that a short-term solution can contribute to a long-term strategy when it is designed as a learning step. Its limitations were not hidden; they became inputs into the next release.
V3: Build a flexible, visual Workflow system
As V1 and V2 were implemented, I continued designing the longer-term Workflow Builder and aligning with front-end and back-end engineers. Once the underlying structure was ready, we moved from a prescribed sequence to a visible, editable system.
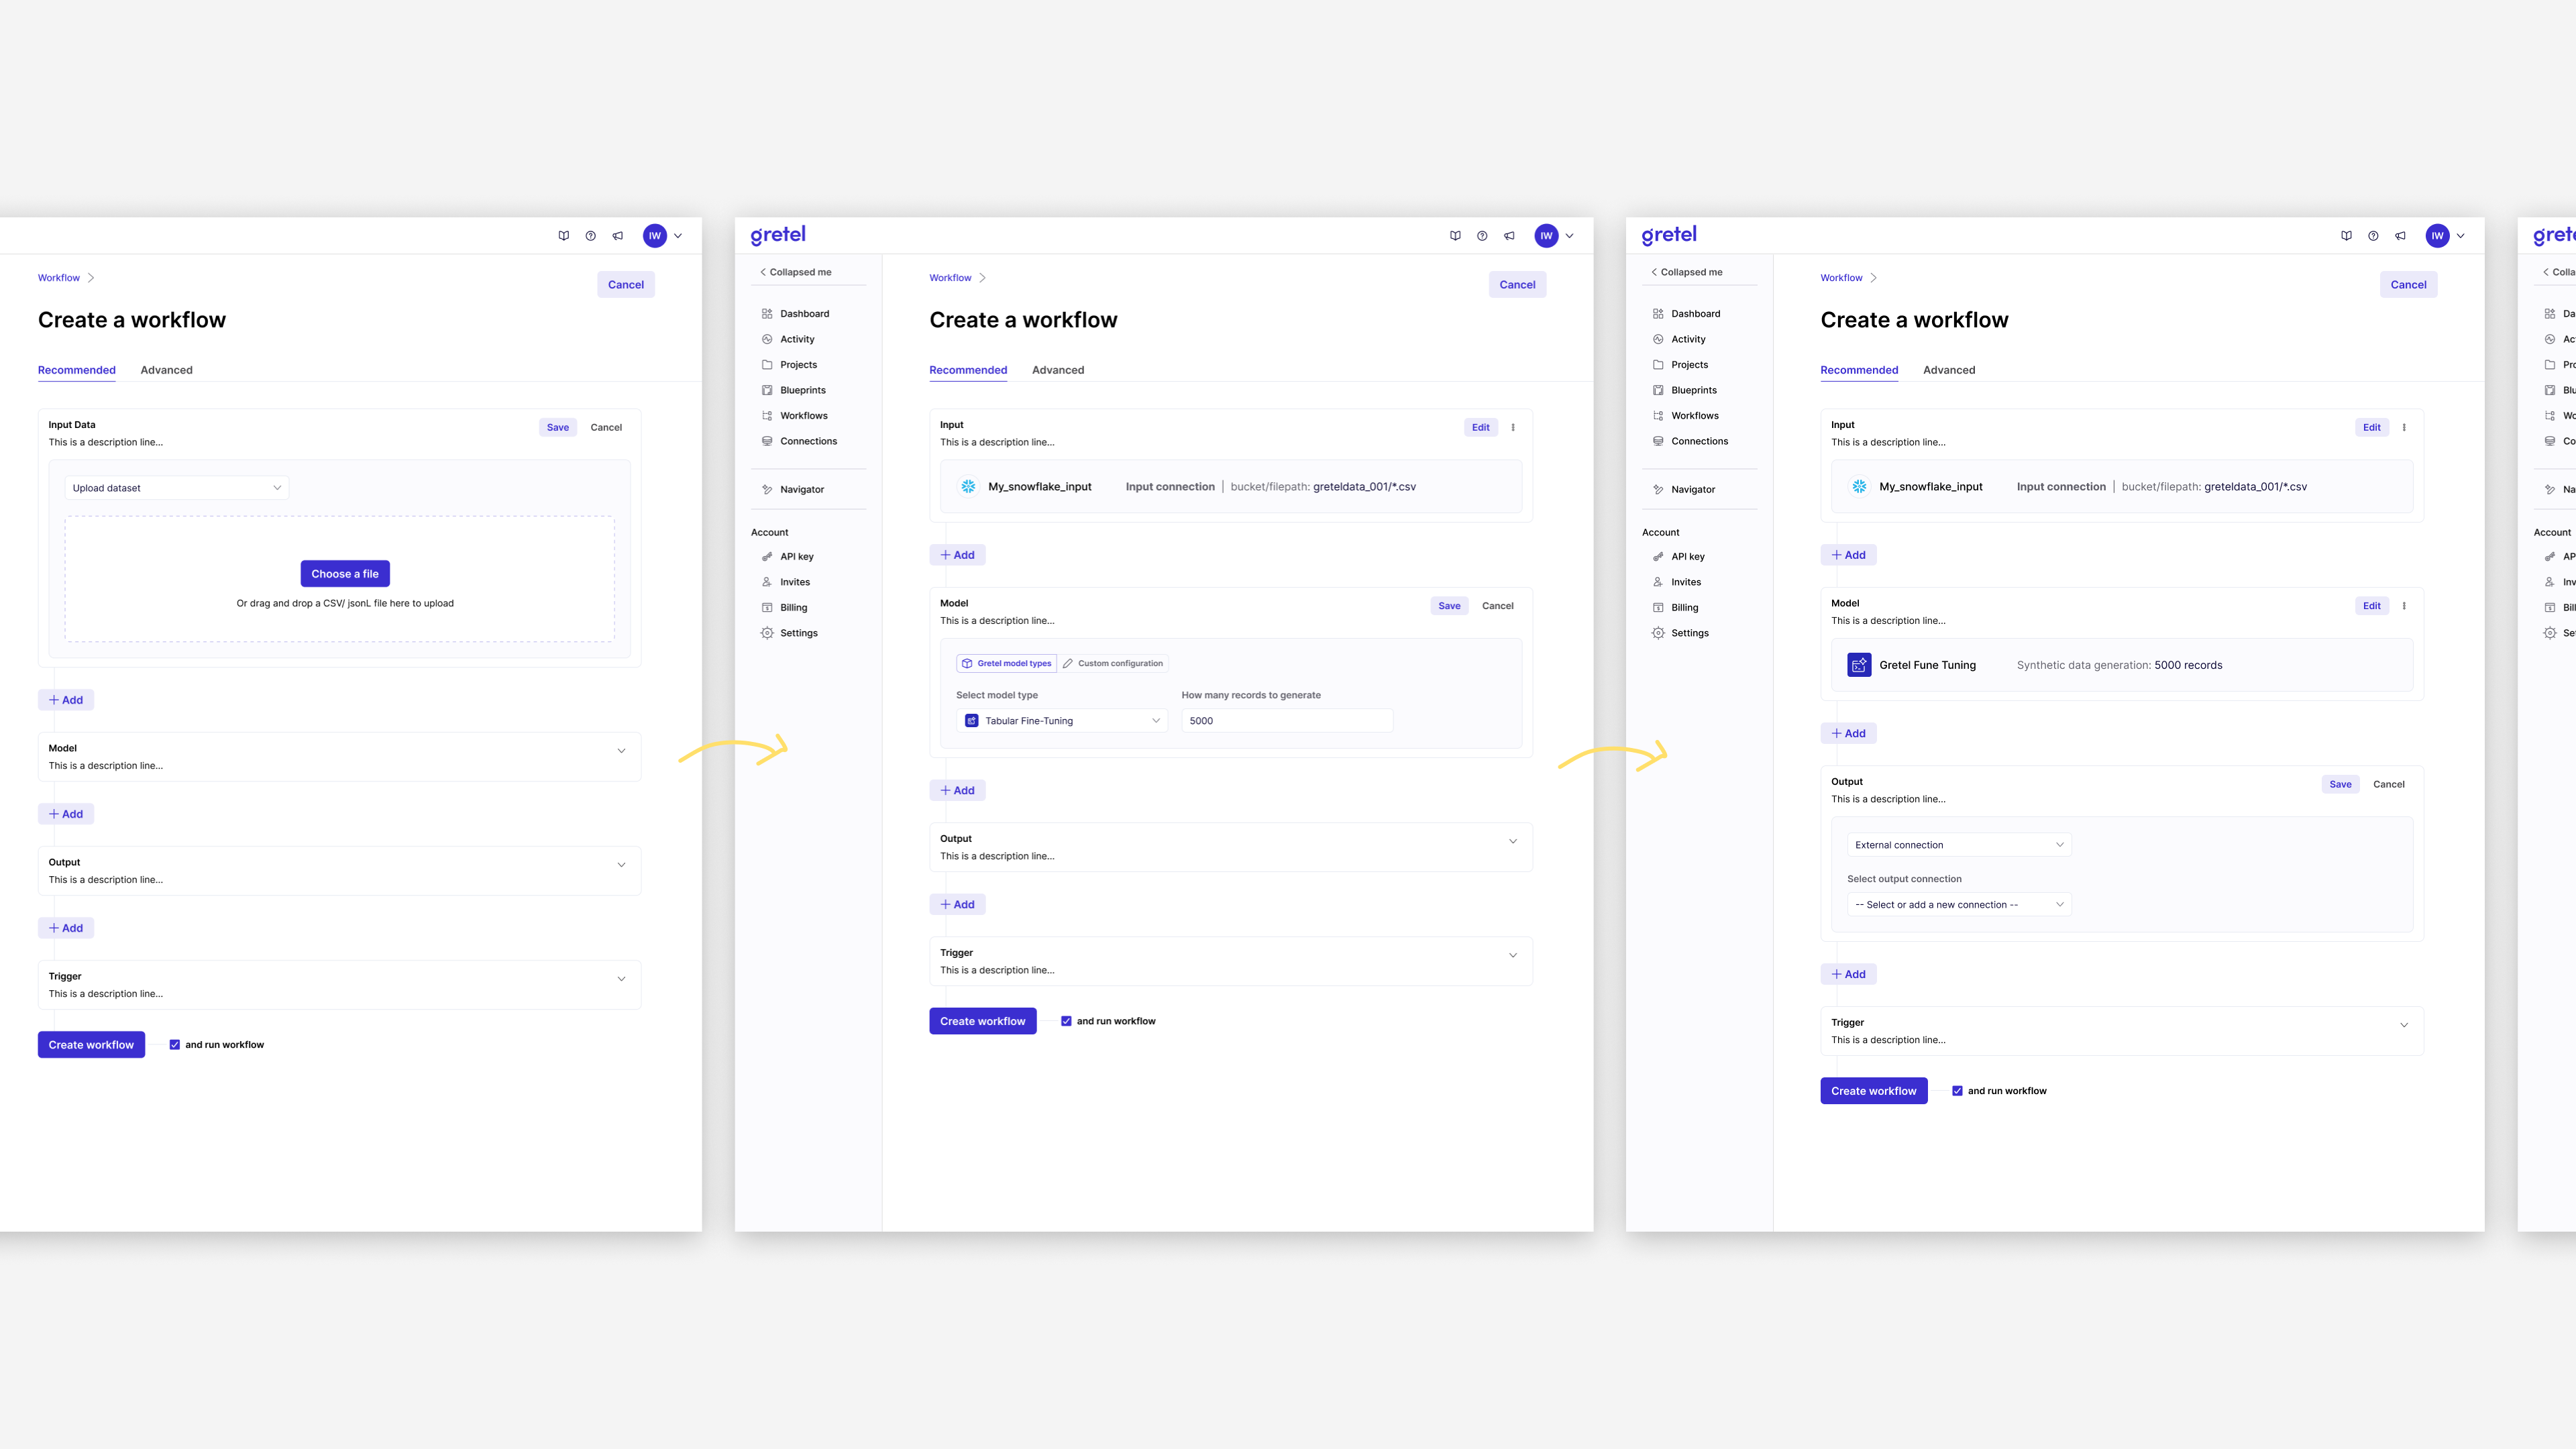
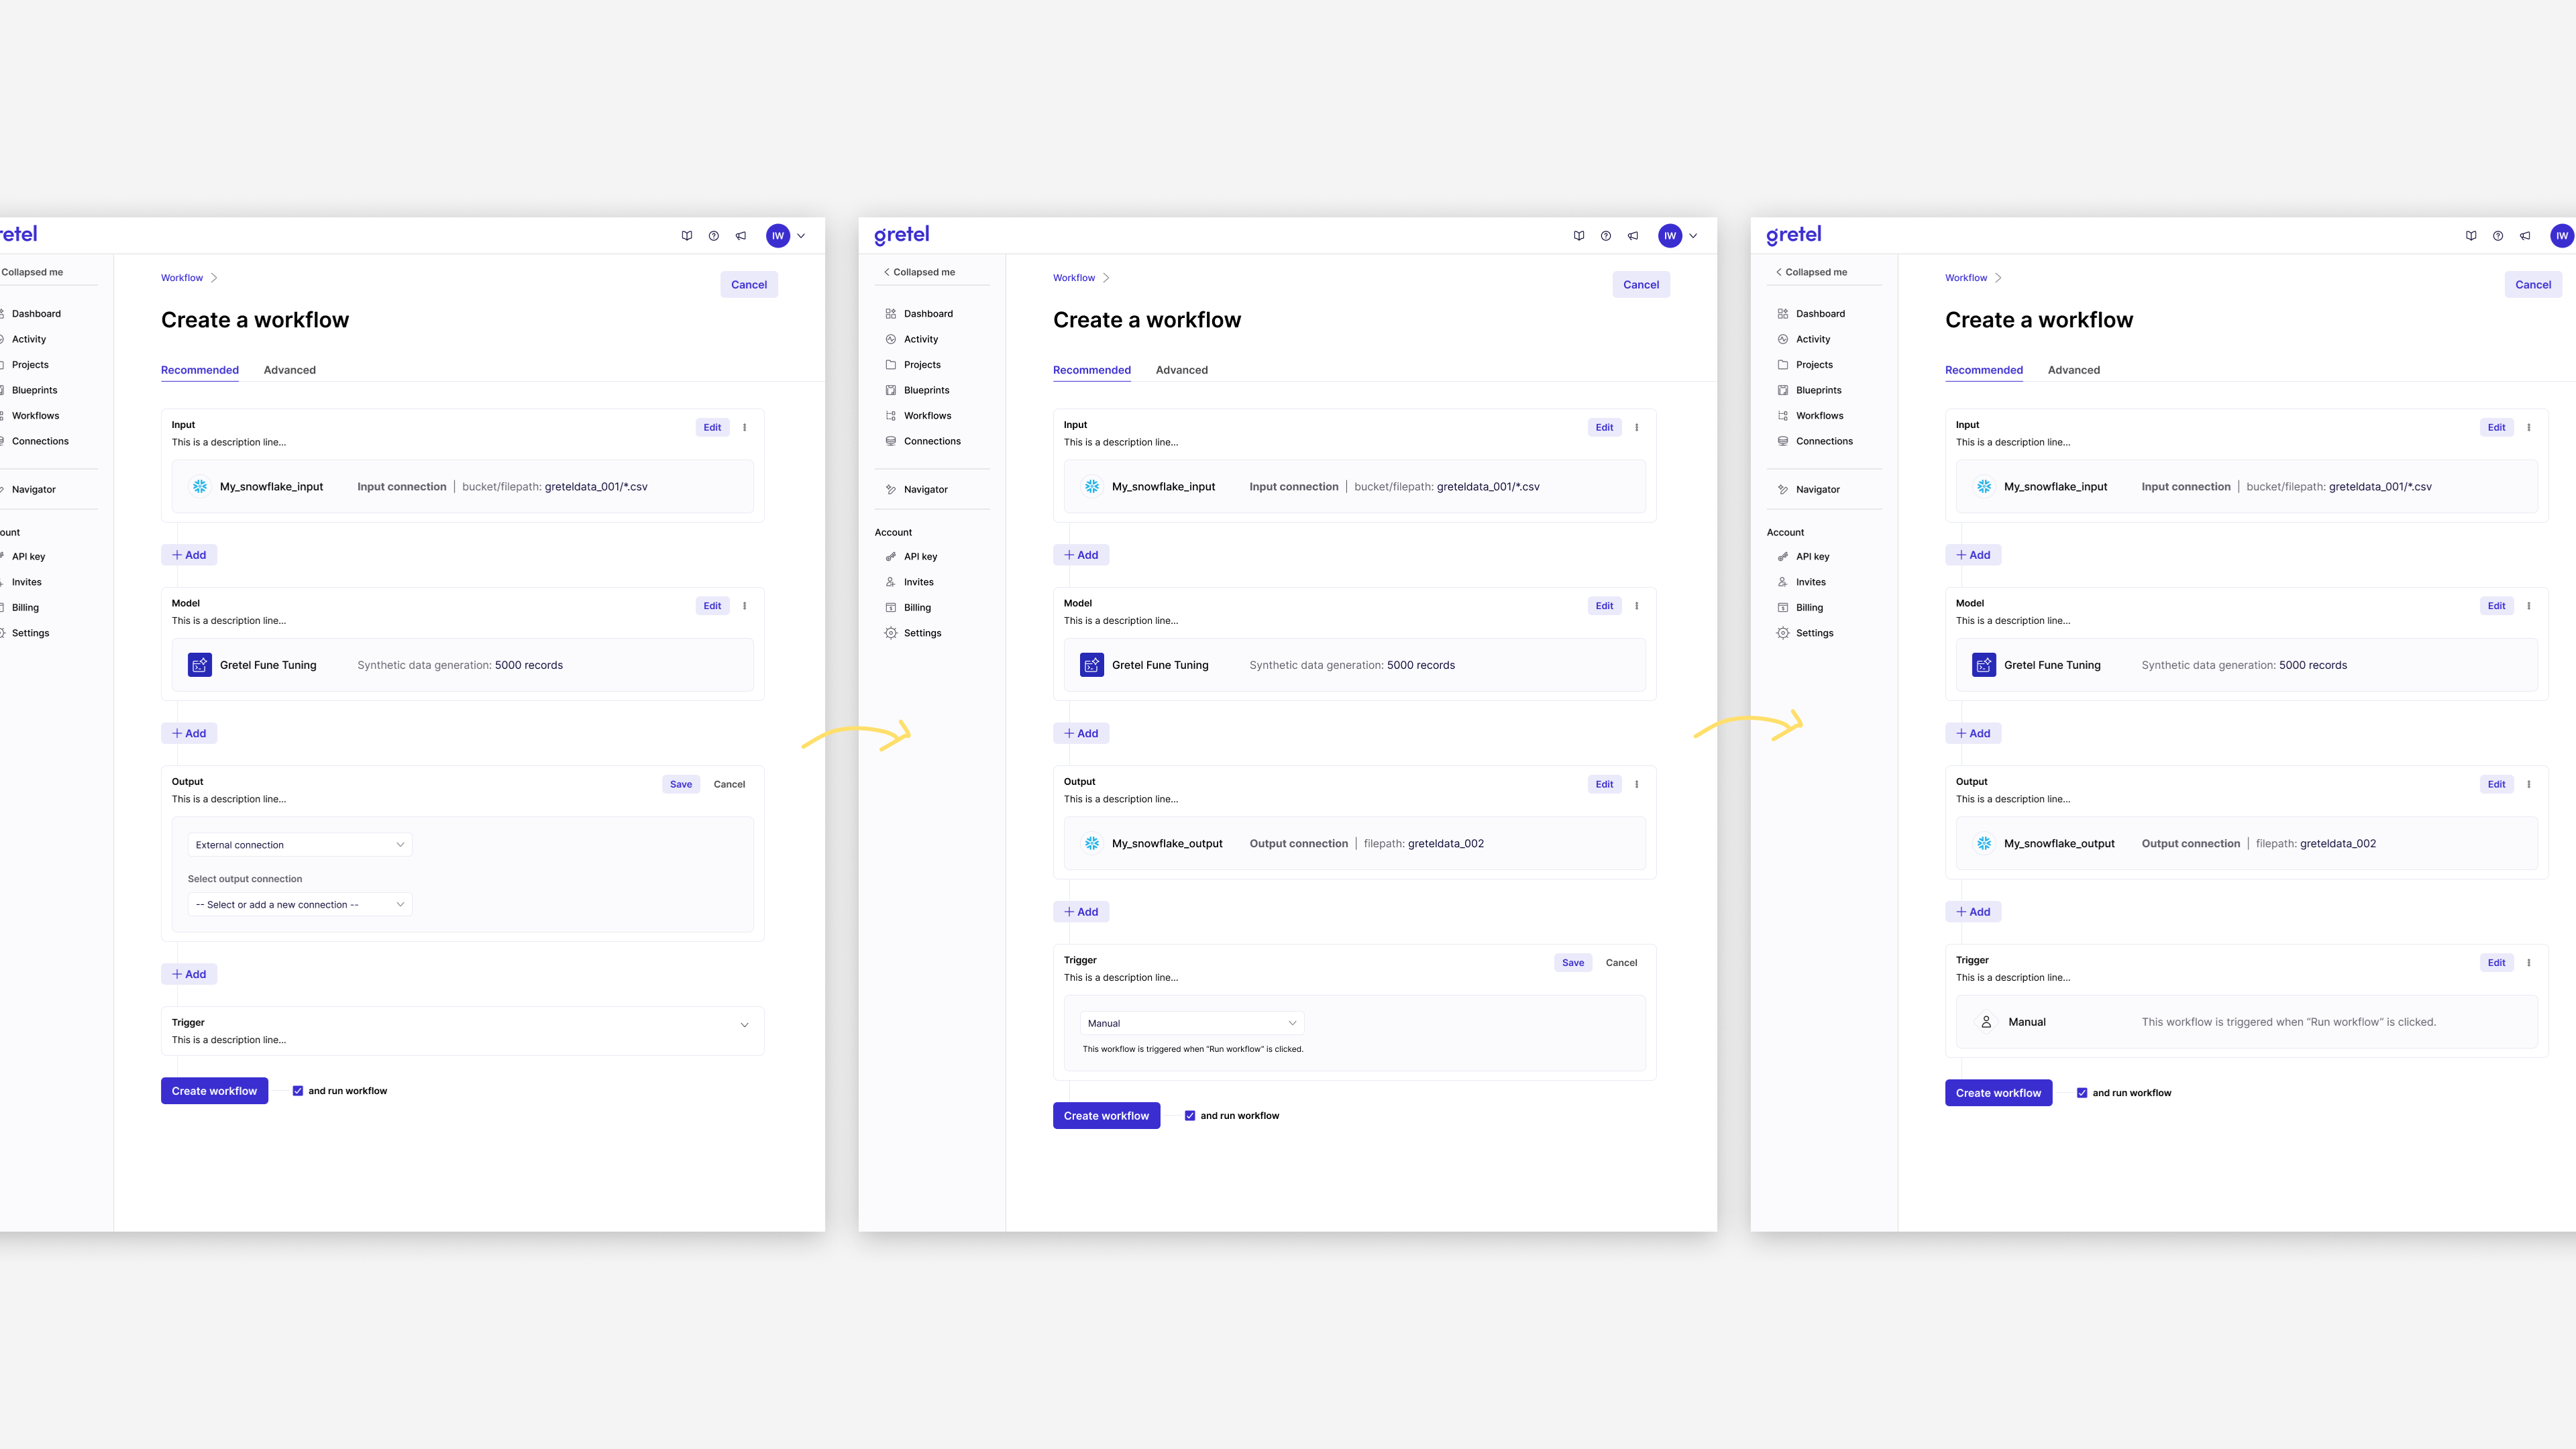
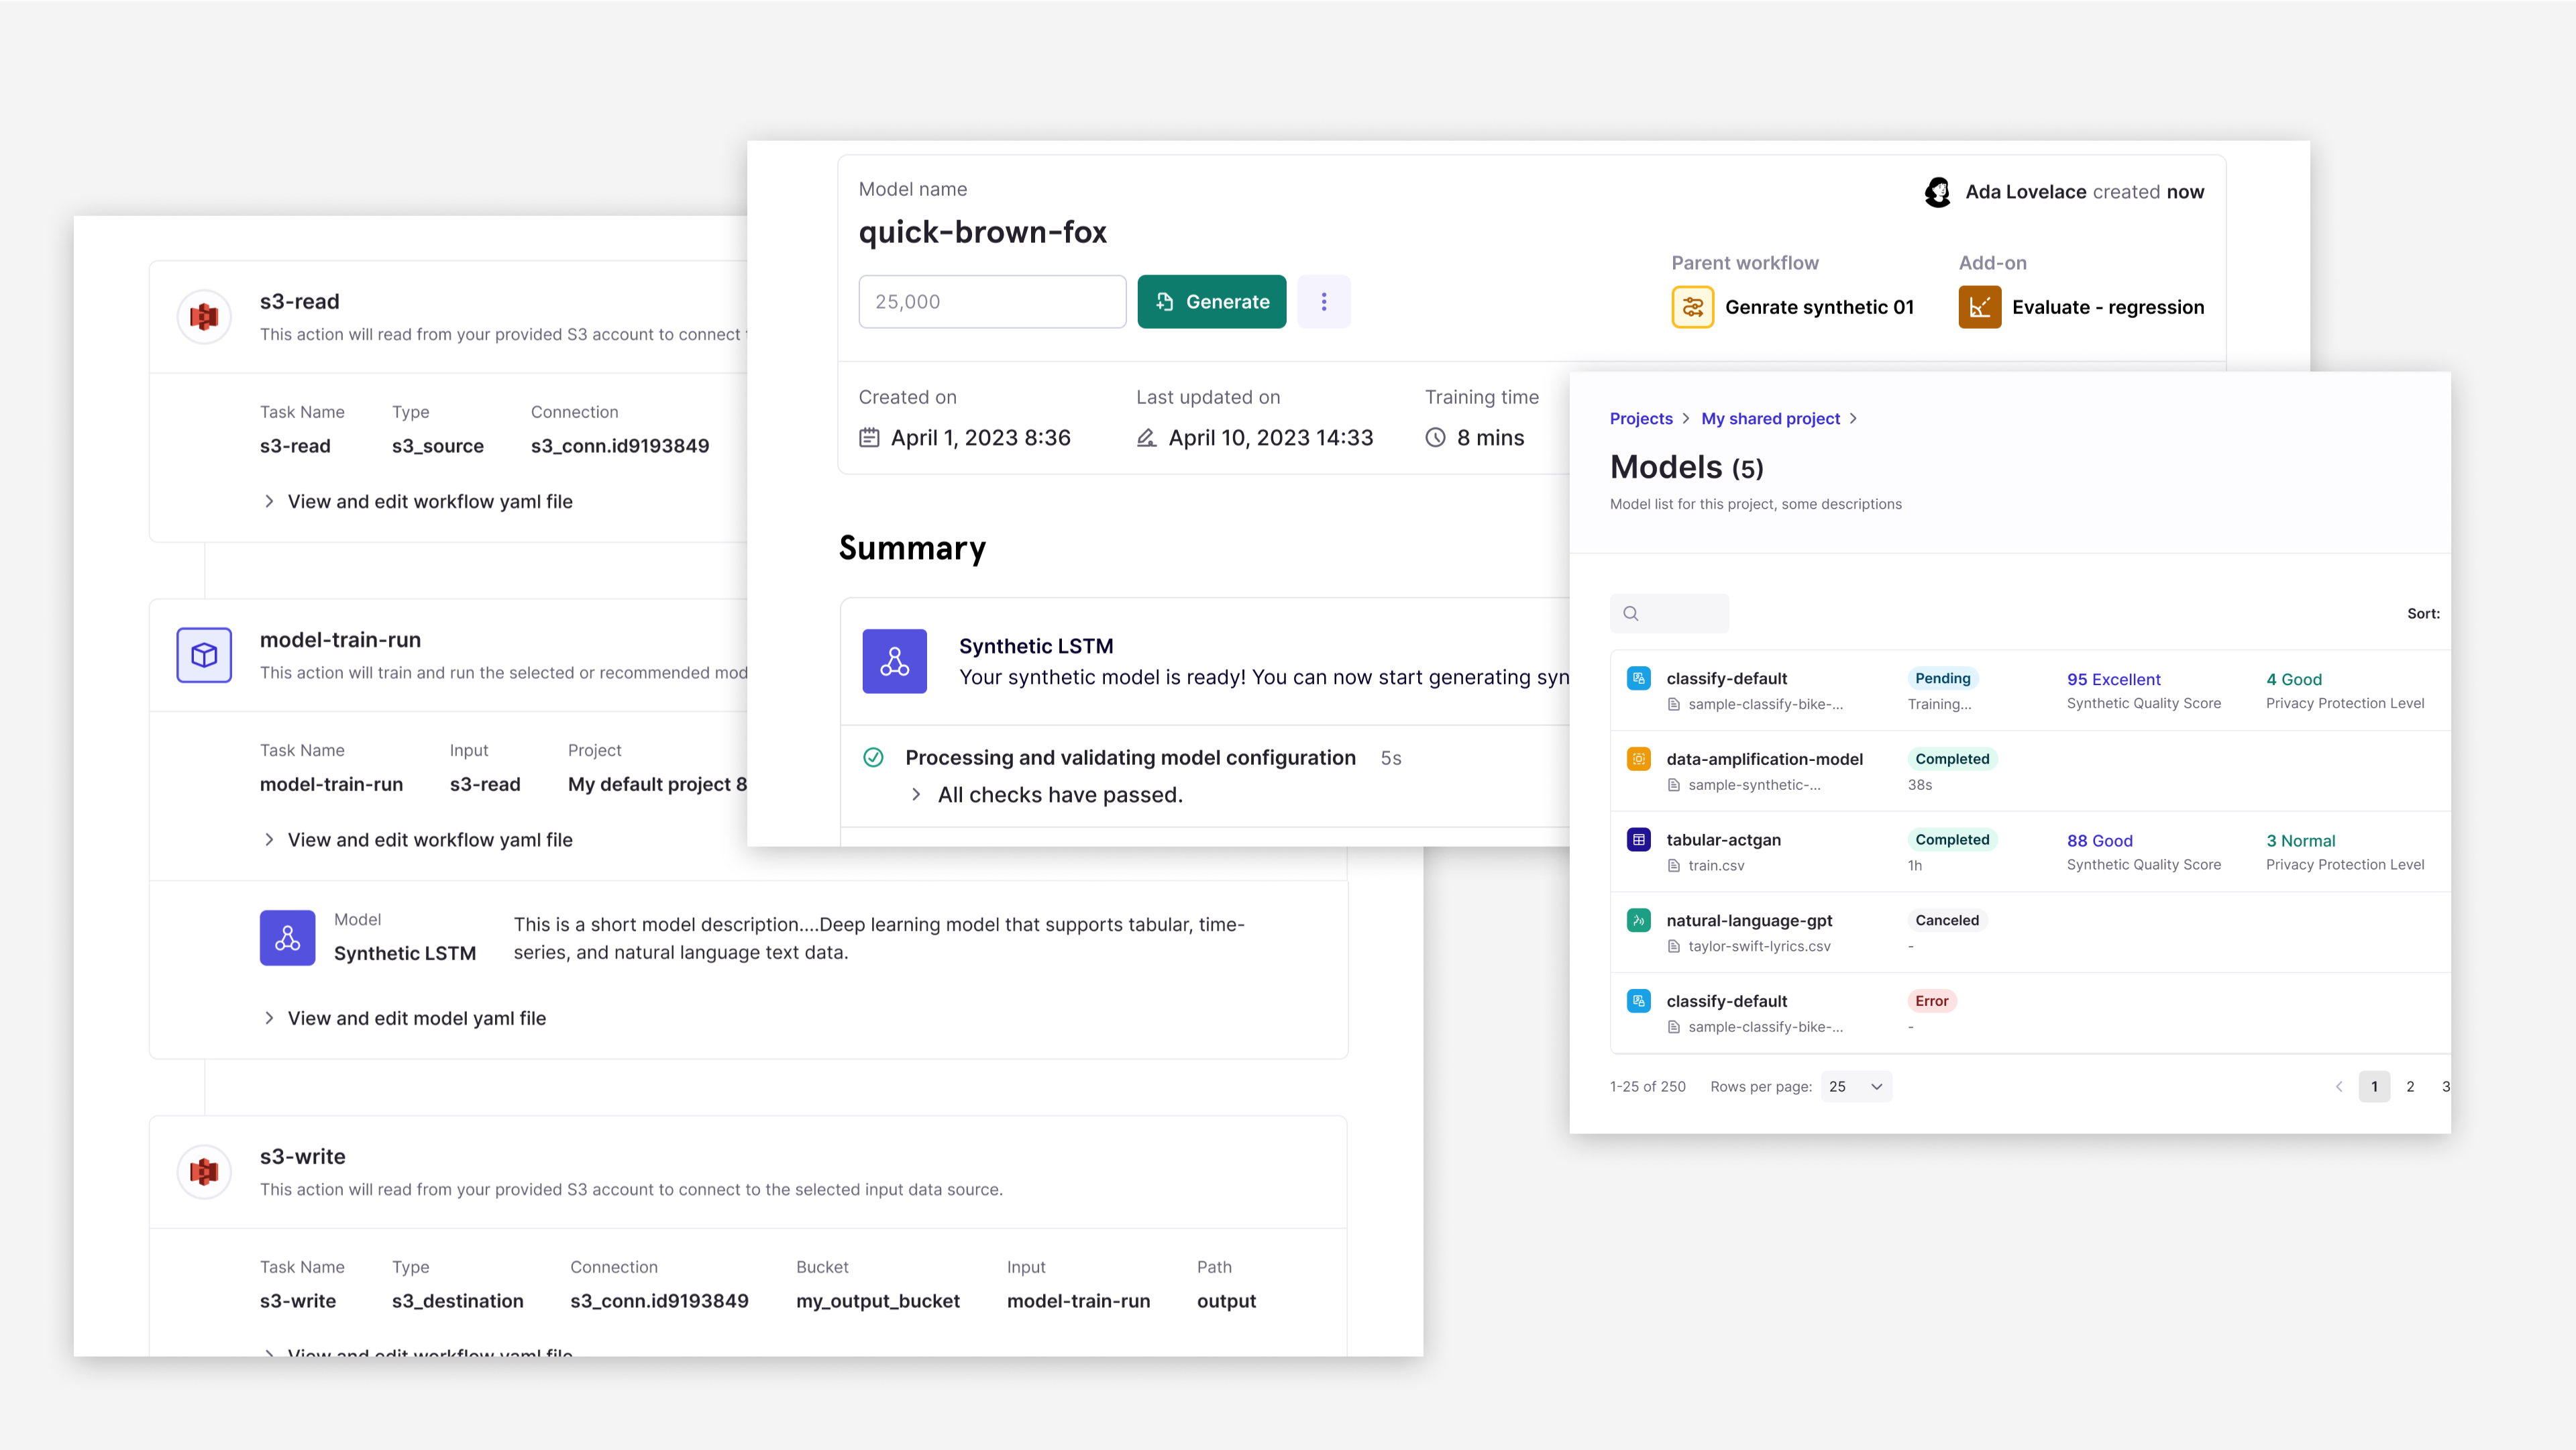
Replace the multi-page flow with a one-page builder
The stepper had provided valuable guidance, but it became restrictive as workflows gained more parts. Users needed to understand relationships across the pipeline, revisit earlier decisions, and edit several steps without moving repeatedly between pages.
I designed a one-page, card-based builder in which each data connection, model, output, schedule, or optional task became an independently editable module. Users could see the entire workflow at once and add, remove, reorder, or update steps while retaining the context of the larger system.
The important shift was not simply multi-page to one page. It was: A prescribed sequence became a visible, editable system.This structure could support both a basic single-model workflow and more advanced model chains without creating a separate interaction for each use case.
Create a reusable visual language
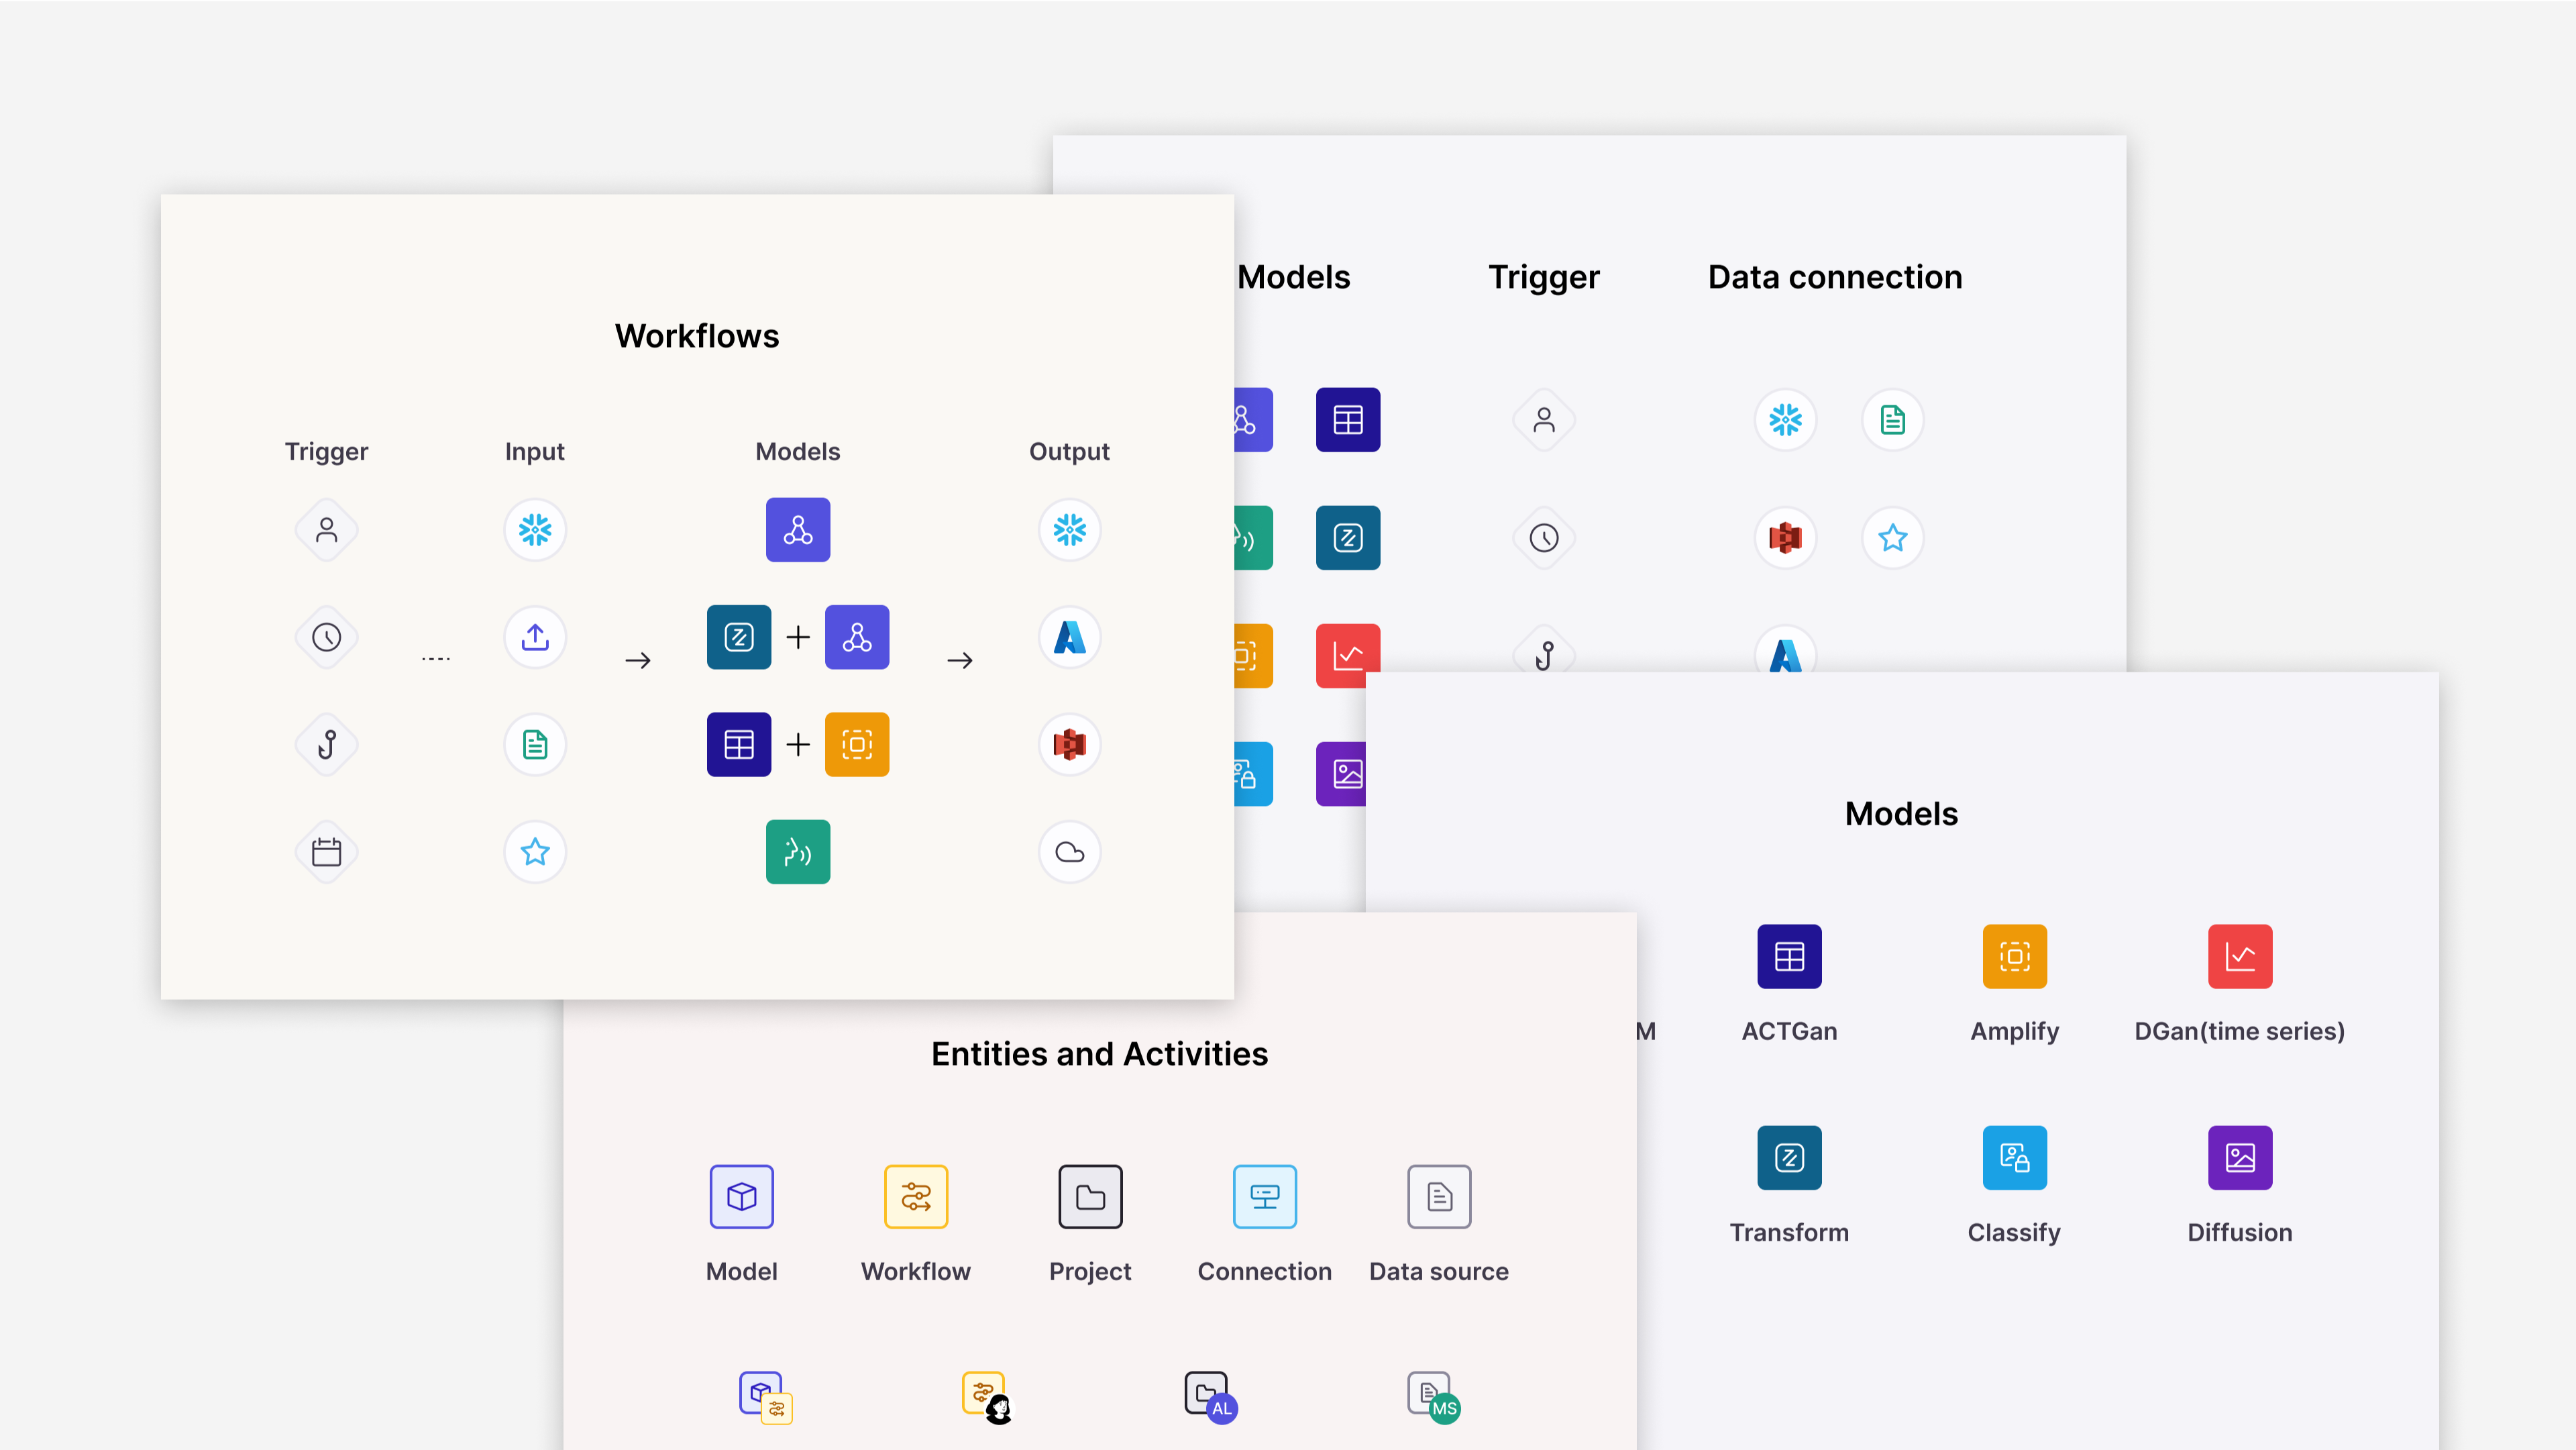
Workflow brought together several unfamiliar object types: data sources, model types, database connections, destinations, schedules, and optional tasks. Text labels alone made the system difficult to scan and the relationships hard to remember.
I grouped the objects into recognizable categories and designed an interconnected icon system using consistent shapes and styles. Tooltips and contextual explanations reinforced unfamiliar terminology while users worked.
The icons were not decoration. They helped users recognize what each object represented, distinguish one kind of step from another, and build a mental model of how the pieces connected. Because the language was reusable, it also gave the product and design system a scalable foundation for future workflow capabilities. The system was well received by both users and internal stakeholders and became a recurring part of the Gretel interface.

Translate common YAML configuration into familiar controls
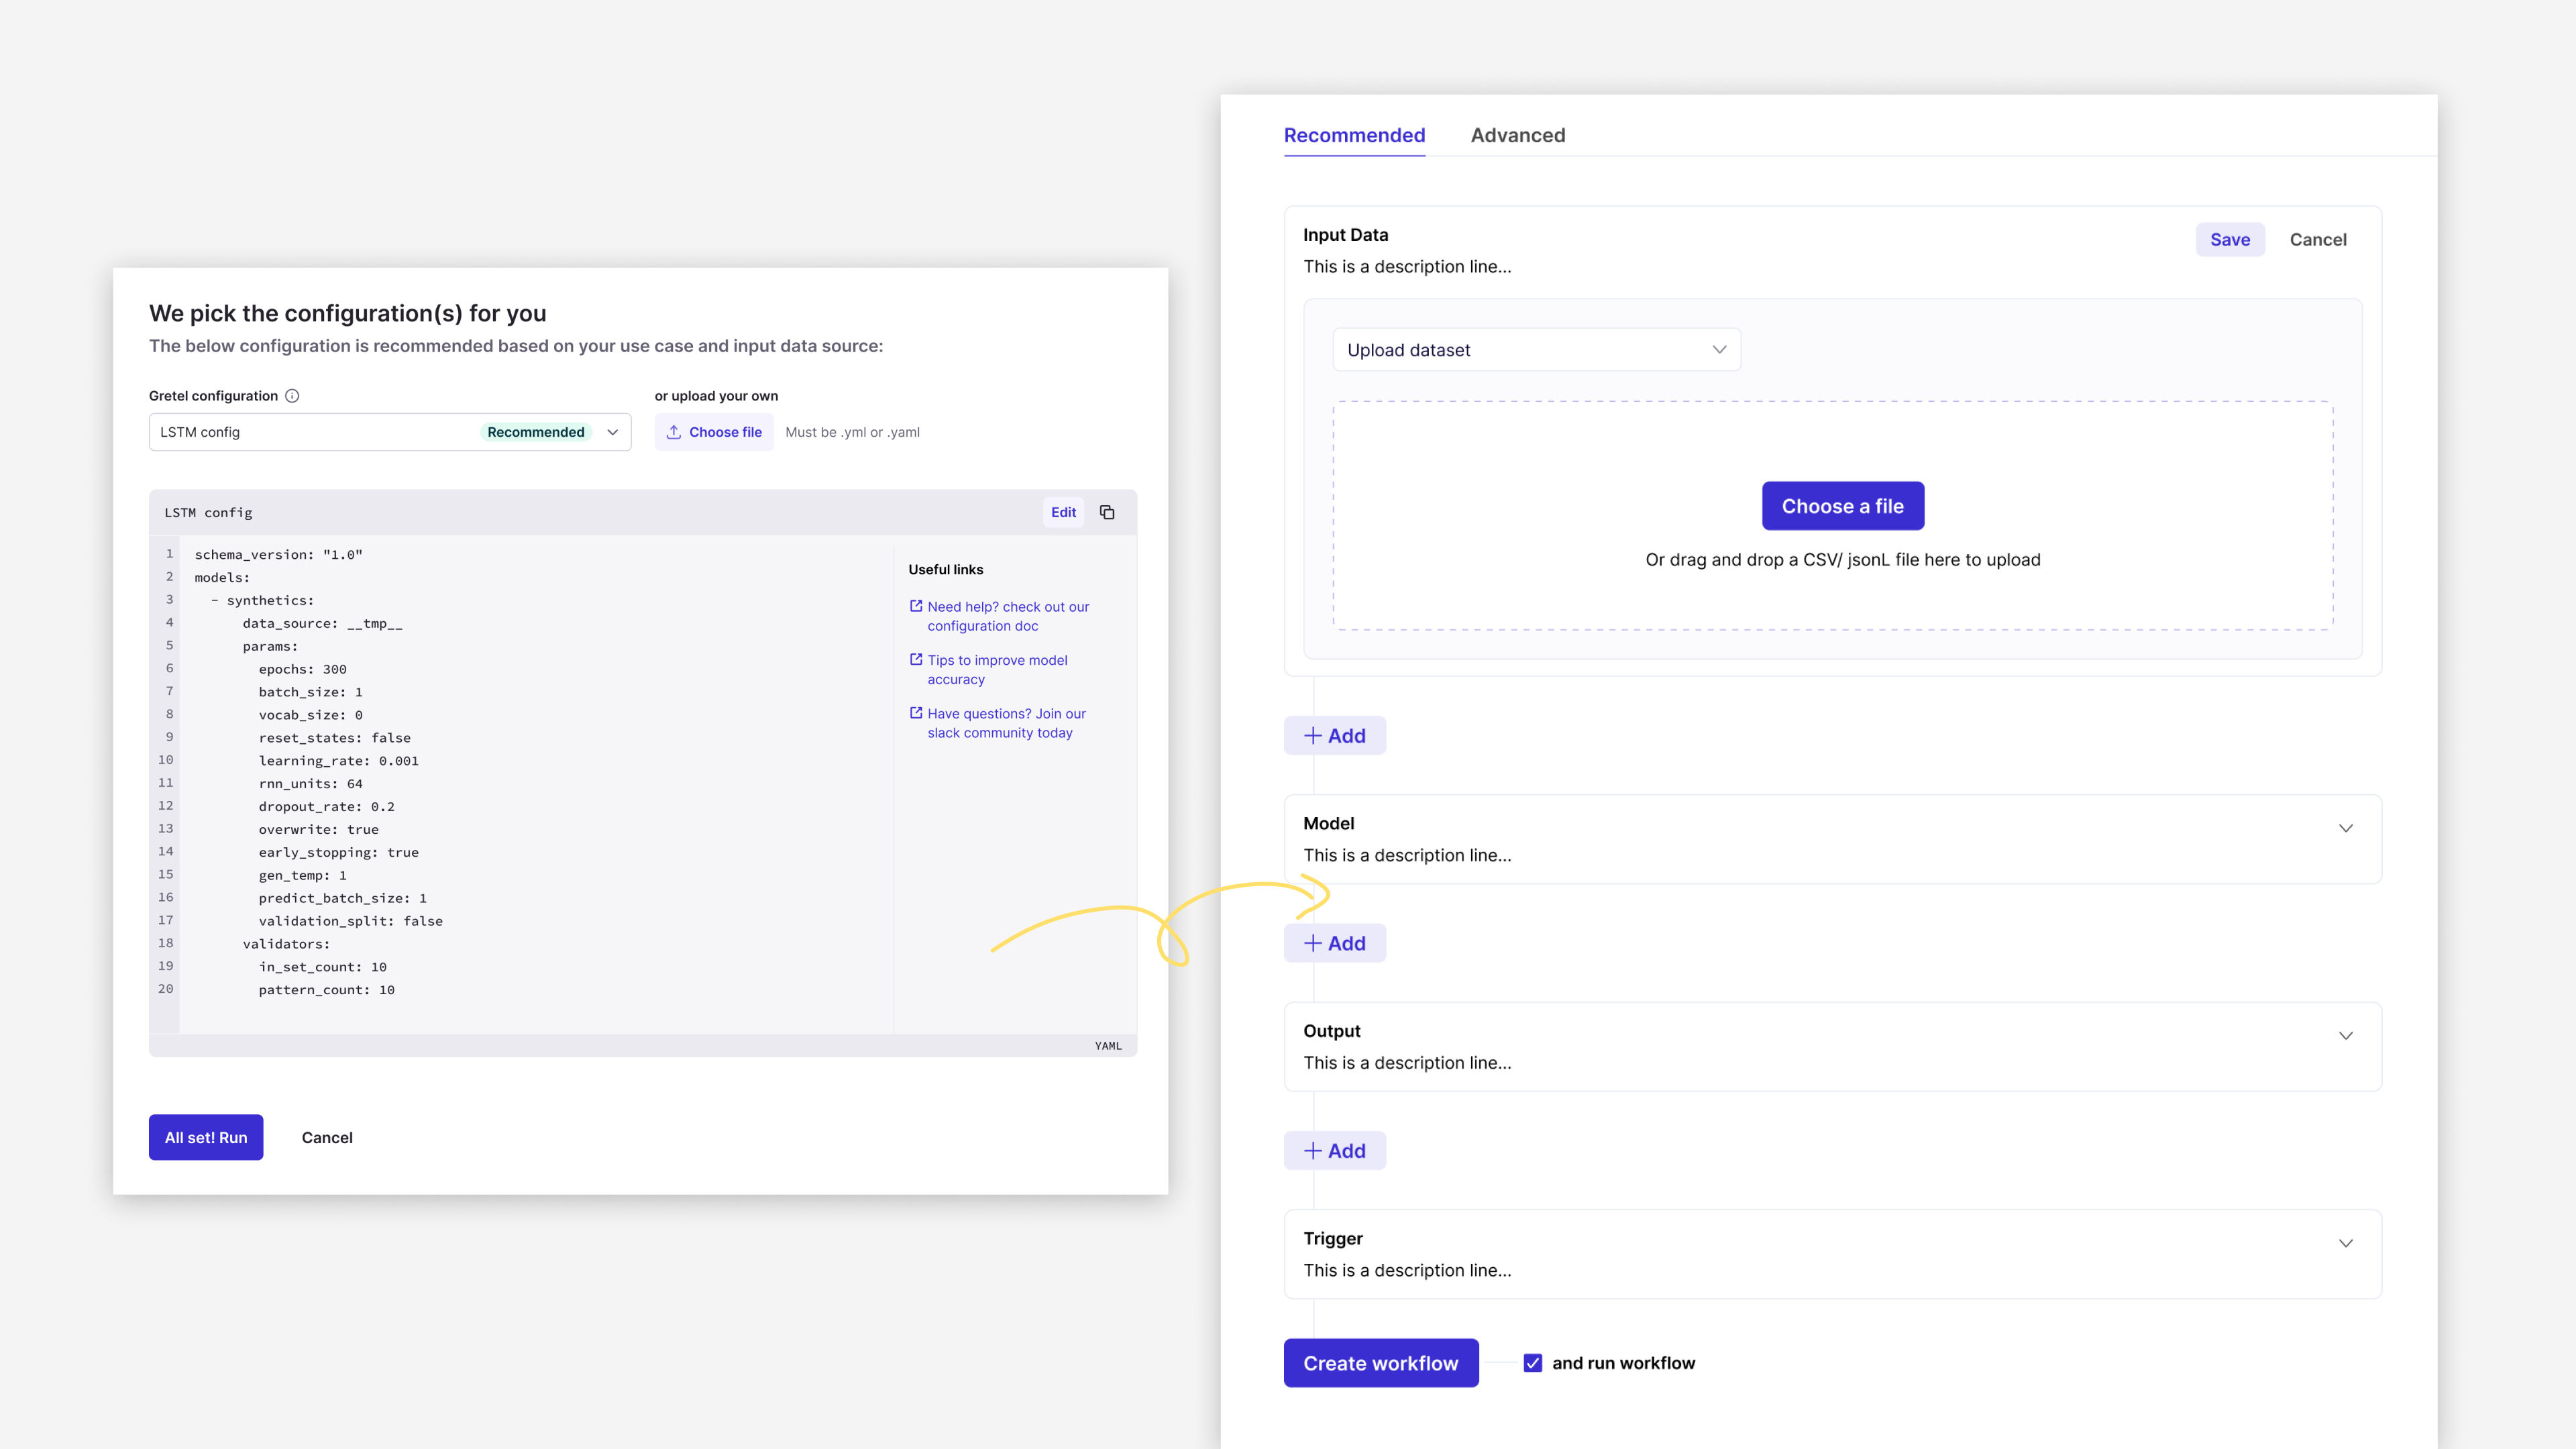
The underlying models still required sophisticated configuration, but most users did not need to manipulate every setting as code.
I progressively translated common configuration properties into familiar UI components such as cards, inputs, dropdowns, selectors, toggles, and file controls. This made the relationship between an action and its effect more legible and reduced the need to memorize syntax or consult documentation for routine decisions.
Advanced YAML editing remained available for experienced users and edge cases. The objective was not to remove technical power; it was to match the interaction method to the task and to the user's level of expertise.
This work required continued coordination with Engineering. As APIs and metadata became available, additional properties could move into the visual interface without breaking advanced configurations or promising controls the back end could not support.
Design validation around independent workflow steps
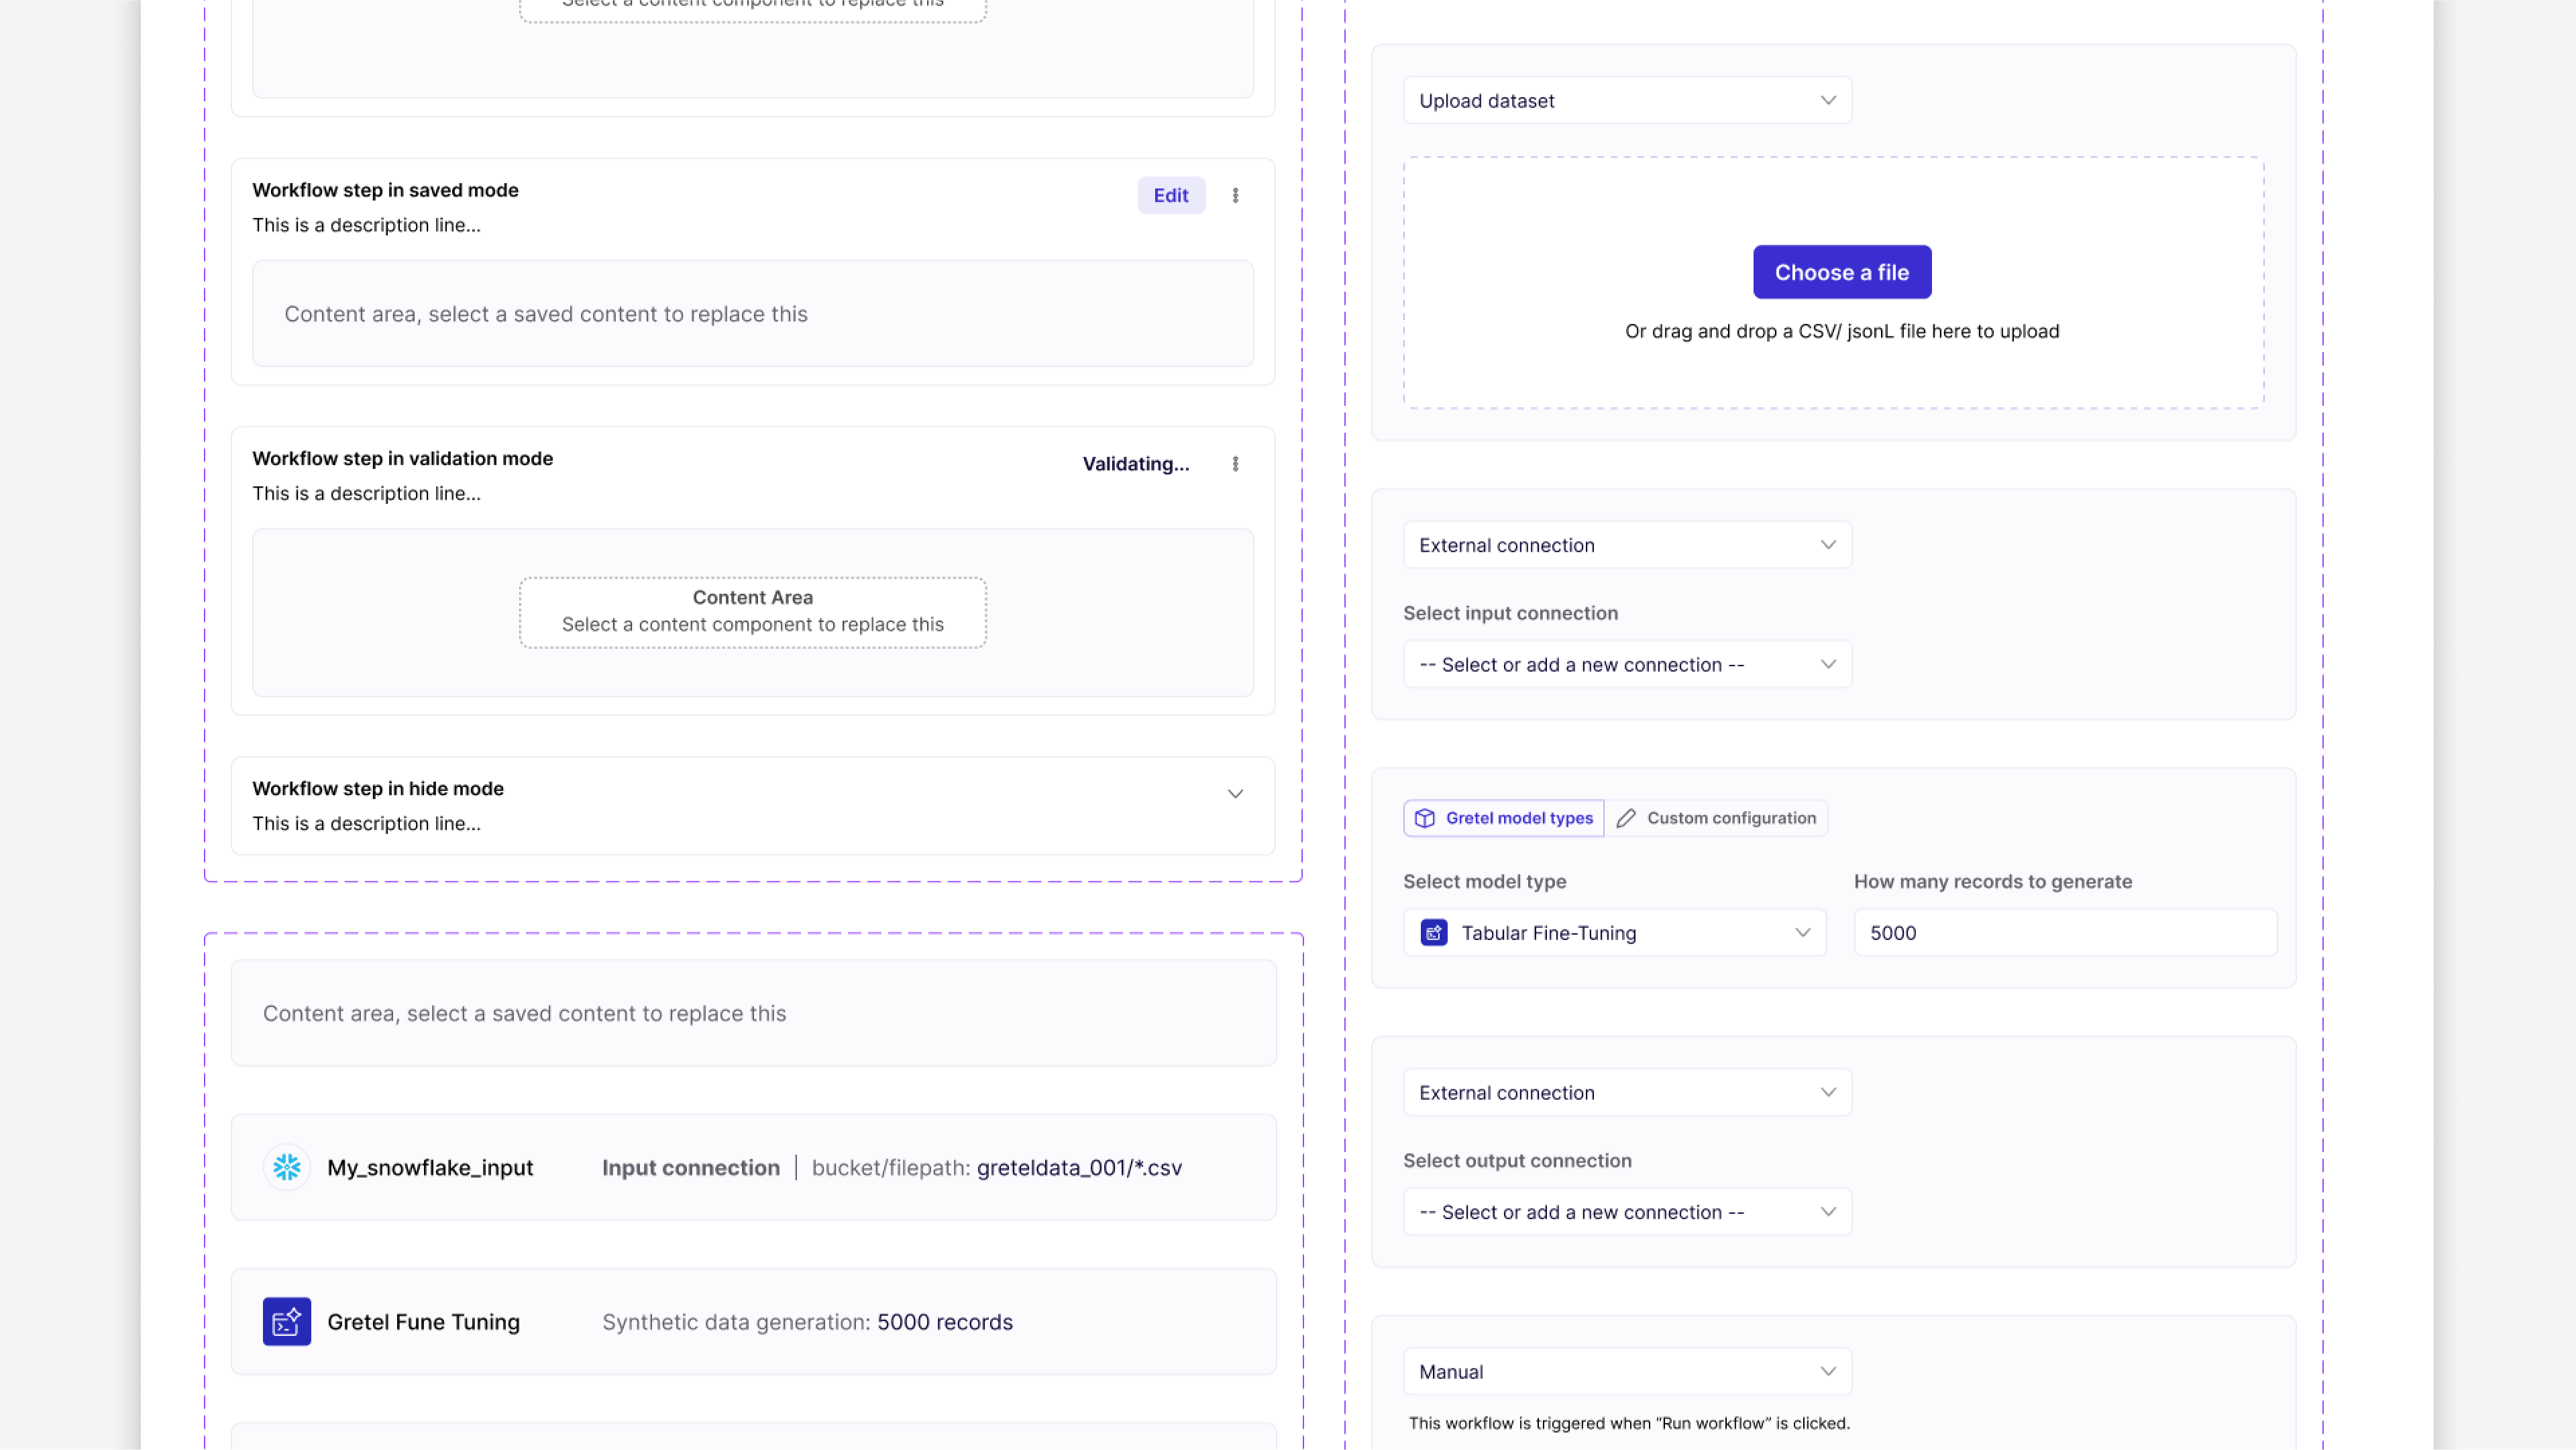
Automation needed more than a generic error message after execution. Users had to understand whether every part of the workflow was ready before they committed time and credits to a run.
I designed a per-step validation model with clear states:
- Validating: the system is checking the configuration.
- Verified: the step is ready to run.
- Attention required: a specific issue must be resolved.
When a step required attention, the relevant card and input surfaced the problem directly. Users could understand what was wrong, where it occurred, and what action to take without searching through an entire YAML file or restarting the workflow.
This was a strategic change in when the product helped the user, expressed through detailed decisions about states, messages, placement, and recovery.
How I turned continuous communication into product strategy
This project required many hours of communication, but the value did not come from scheduling more meetings. It came from knowing which context was missing, who held it, and which people needed to make a decision together.
I kept working groups intentionally focused. A question about customer priorities might require Product and a customer-facing teammate. A question about metadata, APIs, or validation needed the relevant back-end engineer. A conversation about model quality could require Data Science. Bringing the smallest useful group together made discussions more specific and decisions easier to carry into the work.
Throughout the project, I moved through a repeating loop:
- Gather context from customers, analytics, support, technical partners, and existing product behavior.
- Identify the uncertainty preventing a sound design or product decision.
- Find the right person or evidence to resolve it.
- Translate what I learned into risks, dependencies, priorities, and experience principles.
- Define the smallest valuable release that could reduce risk or generate useful learning.
- Design and validate the interaction, then use the result to update the longer-term direction.
This meant V1, V2, and V3 were not isolated redesigns. Each release connected immediate customer value to a broader system plan:
- V1 made the core task reliable enough to automate.
- V2 tested the workflow concept and delivered an early automation loop.
- V3 introduced the flexible structure, visual language, and validation model required for scale.
My role was to maintain that connection between the present constraint and the future experience. I represented user needs, understood enough of the technical system to design credibly, and used both to help the team decide what to build next.
Results
The redesign improved both the immediate model-building experience and the foundation for Gretel's automated workflows.
- Successful model creation increased from approximately 65% to 87%.
- More than 85% of new users used sample datasets to begin, validating the need for a lower-friction path into the product.
- The team delivered a minimum automation experience while the longer-term workflow architecture was still being developed.
- The one-page builder replaced a rigid sequence with a modular structure that could support connections, schedules, independent steps, and multi-model use cases.
- Earlier and more specific validation helped users resolve configuration problems before spending time and credits on a run.
- A reusable icon system and UI-based configuration made technical concepts easier to recognize and interact with while retaining advanced YAML access.
Just as importantly, the project changed the relationship between users and the system. Instead of requiring customers to understand the implementation before they could act confidently, the interface increasingly helped them learn the system through use.
- AI Makes Design Decisions More Important
- Are We Asking the Right UX Questions About AI?
- Designing the First Generative AI Platform for Tabular Data
- From Dashboard to Design System: Thriving as a Sole Designer in a Product-Driven Team
- Improving the Sign-up Process for Pending users
- The Beauty of design